
Website & Development
Building a Website for AI Search: The Technical B2B Guide

Copy for AI
Building a website for AI search means making your pages readable for AI engines.
The verdict: put your core content in the first HTML response, give it a clear structure, add structured data and keep the site fast and crawlable. That’s generative engine optimization at the build layer.
The goal is simple. ChatGPT, Google AI Overviews, Perplexity and Gemini should be able to retrieve, understand and cite your content without friction.
Below: which technical choices matter, and how they connect to your GEO strategy. It’s part of our broader guide on building a B2B website.
Quick test: score one of your pages with our free GEO checker.
What does “building for AI search” mean?
It’s aligning your website build with how AI engines read the web, so your pages become the source an answer refers to.
It’s the foundation beneath GEO (generative engine optimization).
GEO is about content, authority and mentions. But without a site machines can read, none of that content ever arrives.
Three hurdles before a citation
An AI engine can only cite your page if it clears three hurdles:
- the crawler has to be allowed in
- the content has to be readable in the raw HTML
- the structure has to show where the answer lives
If any one of those fails, your content simply doesn’t exist for the model:
The rest of this article walks through those hurdles, one by one.
Why is server-side rendering important for AI crawlers?
Because most AI crawlers don’t run JavaScript.
That’s the most important technical reality of AI visibility.
What Vercel found in crawler traffic
Vercel analysed AI crawler traffic across its network. GPTBot, ClaudeBot and PerplexityBot fetch HTML, but “none of the major AI crawlers currently render JavaScript” (Vercel, The rise of the AI crawler).
They aren’t small players either.
In one month on Vercel’s network, GPTBot sent 569 million requests and Anthropic’s Claude 370 million:
What a crawler sees on a single-page app
The consequence is concrete.
Build your site as a single-page application, where content is only assembled in the browser, and such a crawler often sees a virtually empty page.
For classic SEO, Googlebot partly compensated by still rendering pages.
Vercel notes that Google’s Gemini leans on that same Googlebot infrastructure, and AppleBot renders JavaScript too.
But most other AI engines don’t.
Whatever isn’t in the first HTML response doesn’t exist for them.
Our deep dive on client-side rendering and AI search shows what that looks like in practice.
The fix: SSR or static generation
The solution is server-side rendering (SSR) or static generation.
The server delivers the full content as HTML, ready to be read.
Frameworks and platforms differ greatly in how well they do this by default.
That’s why the build choice weighs more heavily here than people assume.
You can check it yourself in under a minute.
Open a page, choose “view source” and search for your core message:
How does your site structure help AI understand your content?
A clear, shallow structure with meaningful headings shows an AI engine where the answer to a question sits.
AI models don’t read content the way a human scans a page.
They cut your text into chunks and look for the fragment that best answers a question.
The more clearly you mark off that fragment, the greater the chance it gets picked up.
Our guide to content chunking for AI goes deeper.
Three structure habits
Three things help:
- Headings: use H1, H2 and H3 as real questions or clear topics, not wordplay
- Answer first: open each section with a self-contained answer of one or two sentences
- Flat architecture: keep every important page a few clicks from the homepage
For example, a section titled “How long does an ERP rollout take?” should open with the timeframe, not with a story about your company.
Internal links connect the topics
Keep your website architecture flat enough that every important page is reachable in a few clicks.
Internal links should connect related topics logically. Google’s own AI features guidance lists internal links and keeping important content in text among its recommended practices.
That structure serves visitor and machine alike.
A human finds the answer faster, and a crawler understands what your site is about faster.
There’s a second reason.
Google says AI Overviews and AI Mode may use “query fan-out”: several related searches across subtopics. For example, a buyer’s question about ERP pricing may fan out into searches on licences, implementation and support. A site that answers those subtopics on clear pages has more chances to be picked.
Our explainer on query fan-out covers how that works.
What role does schema markup play for AI?
Schema markup translates your content into a format machines read unambiguously.
That lowers the chance of misinterpretation.
With structured data you state it explicitly. This is an article, this is the author, this is a question with this answer, this is our organisation.
The engine then doesn’t have to guess it from loose text.
JSON-LD and the types that matter for B2B
The recommended format is JSON-LD, a block of code that sits in the page separately from your visible HTML.
It’s the easiest format for engines to process, because it’s neatly separated from your layout. Important types for B2B:
- Organization: who you are, where you are, how to reach you
- Article: what the page is, when it was updated
- FAQPage: questions with their answers
- Person: the author behind the content, see author schema markup
Our experience: for LLMs, getting cited is more about how often and how consistently other sites mention you. Structured data for organisation, person and product is the baseline, not the finish.
Check what you actually ship
The golden rule: your schema markup must always match what a visitor actually sees on the page.
Otherwise it backfires.
Google says the same in its AI features guidance: make sure “your structured data matches the visible text on the page.”
Here’s that check on our own English homepage, in the Schema Markup Validator:
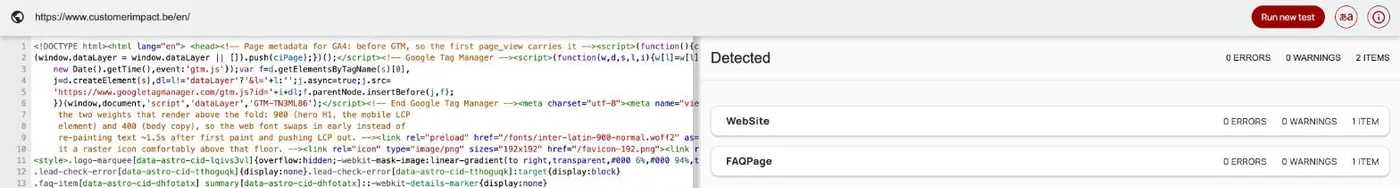 The Schema Markup Validator on our own English homepage, October 2026. Check that each detected type matches what the page visibly says.
Don’t expect miracles from it
Structured data is no guarantee of a citation.
The exact impact varies per engine and is judged differently by different parties.
Google is blunt about its own features: “There’s also no special schema.org structured data that you need to add.”
But it’s a cheap, reliable way to prevent misunderstandings.
That makes it a sensible default during the build.
How important are speed and Core Web Vitals?
Speed partly decides whether a crawler fully retrieves your page and whether a visitor stays.
Slow or heavy pages get crawled less thoroughly.
On the human side, they cost you conversions.
The three thresholds
Google’s Core Web Vitals remain a useful benchmark. Google’s Core Web Vitals documentation sets three targets:
| Metric | Measures | Good |
|---|---|---|
| Largest Contentful Paint (LCP) | Loading | 2.5 seconds or less |
| Interaction to Next Paint (INP) | Responsiveness | under 200 ms |
| Cumulative Layout Shift (CLS) | Visual stability | under 0.1 |
They force you into clean, efficient code.
Here’s how our own homepage scores in the field data:
 PageSpeed Insights field data for customerimpact.be on mobile, October 2026. LCP passes at 1.9 s; CLS at 0.13 still needs work.
LCP passes at 1.9 seconds, well within 2.5. But CLS sits at 0.13 against a 0.1 target, so even a fast site has a metric to fix. Our guide to Largest Contentful Paint breaks down the loading part.
What counts most for AI crawlers
For AI visibility, what counts most is that your server quickly delivers a complete HTML response.
Light pages, optimised images and few render-blocking scripts help directly. A Lighthouse report or our website speed test shows where the gains are.
Good news: what makes your site faster for humans also makes it more accessible for machines. It’s the same technical hygiene.
Should you adjust your robots.txt or llms.txt for AI bots?
Yes: crawl access is a deliberate choice you make explicit in your robots.txt.
If you want AI engines to cite you, their bots have to be allowed to crawl your site.
Search bots and training bots aren’t the same
OpenAI’s crawler documentation splits its bots by job:
- OAI-SearchBot: surfaces sites in ChatGPT search
- GPTBot: collects content that may train OpenAI’s models
- ChatGPT-User: visits a page when a user asks; robots.txt may not apply
Each setting is independent.
So you can block training and still be found in ChatGPT search.
OpenAI adds that a robots.txt change can take about 24 hours to reach its search systems.
Our own robots.txt is a single rule that lets every crawler in:
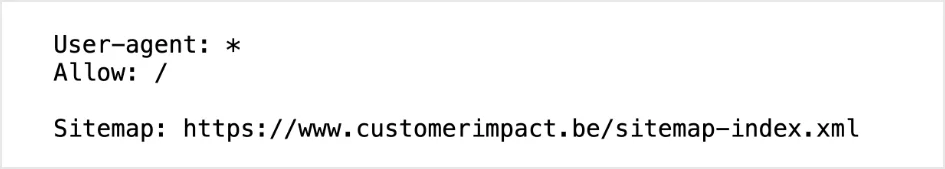 Our own robots.txt, October 2026: one rule for all crawlers, so every AI bot, training and search, may read the site. Add a separate user-agent line only for a bot you deliberately want to block.
You can also deliberately keep certain bots out, for example to stop your content being used as training data.
That’s a strategic trade-off, not a leftover setting. Both sides are covered in allowing AI crawlers and blocking AI bots in robots.txt.
What about llms.txt?
Around the proposed llms.txt file, a kind of table of contents for AI, more restraint is warranted.
Jeremy Howard proposed it on 3 September 2024 (llmstxt.org). It’s a Markdown file with brief background and links to LLM-friendly pages.
It’s a community proposal with limited adoption.
Major AI providers don’t all support it, or don’t even request the file.
Google’s AI features guidance is explicit: “You don’t need to create new machine readable files, AI text files, or markup to appear in these features.”
Rule of thumb: add it as a bet on the future if you like, but don’t count on it as a channel today. More in our explainer on llms.txt.
Invest in the basics first: readable HTML, structure and schema.
Which platform choice suits AI visibility?
No platform is by definition “the best” for AI visibility.
It depends on how well your setup meets the principles above.
Every platform can go either way
Webflow, WordPress and custom or headless solutions can all deliver server-side rendered, fast, well-structured pages.
All three can also be set up poorly. The winner depends on your situation:
- your team
- your content
- your budget
- your growth plans
Our comparison of the best CMS for AI search weighs them side by side.
Our experience: WordPress, Drupal, Webflow and Joomla all used to be really good, and now it depends on the company. AI and digital-native companies are moving to agentic websites: no plugin updates, no security warnings, and languages built and translated programmatically.
Verify it in the source code
What always holds: during the build, choose rendering that delivers complete HTML, a clean structure, structured data and speed. Then actually verify it in the source code.
We’re platform-agnostic and advise on your case, not on a favourite.
Visibility has to reach your pages
Keep the goal in focus.
AI visibility is only worth something if the citations and visitors also reach your website development pages and turn into requests there.
You can measure that.
In our own GA4, chatgpt.com brings a small share of sessions but a much larger share of key events:
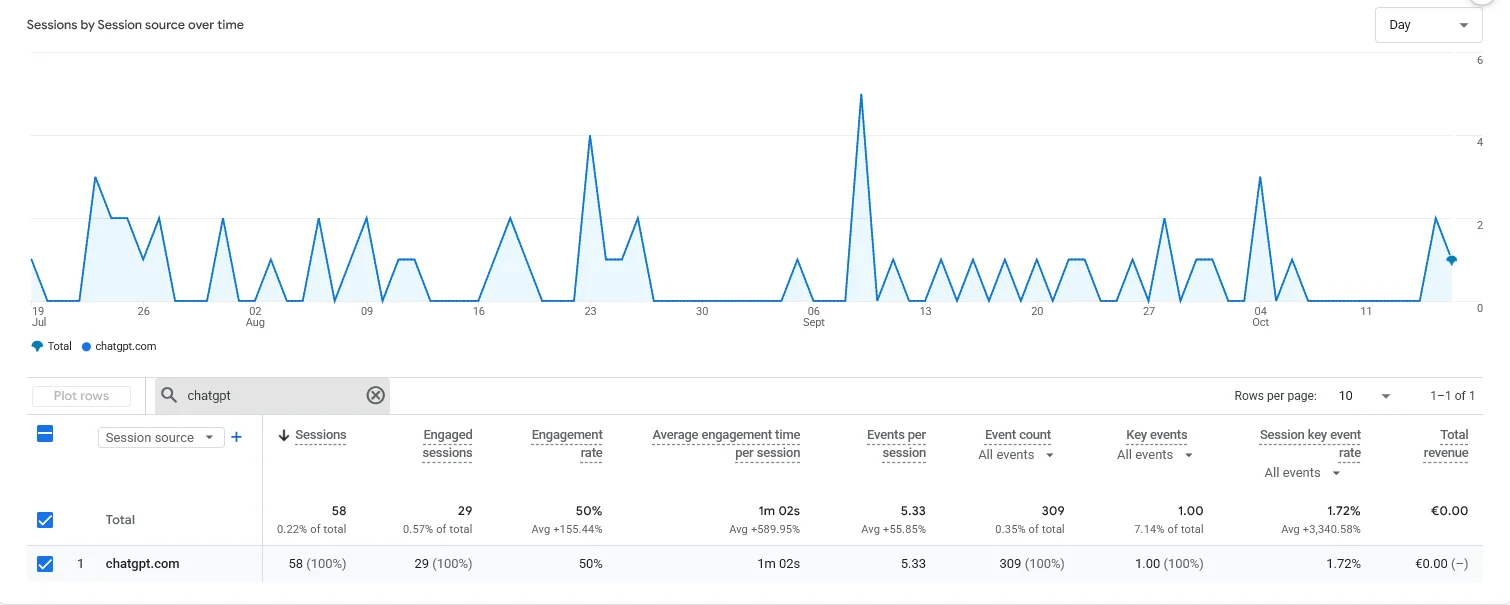 Our own GA4, October 2026: chatgpt.com brought 0.22% of sessions in 90 days, yet 7.14% of all key events.
That’s 58 sessions in 90 days, 0.22% of the total, yet 7.14% of all key events. The setup is explained in how to track ChatGPT traffic in GA4.
The short summary
Building for AI visibility comes down to four technical pillars:
- server-side rendered HTML, so crawlers see your content without JavaScript
- a clear structure with answer-first sections
- correct structured data in JSON-LD
- a fast, crawlable site
Combine that foundation with a well-considered GEO approach and with pages built to convert.
Not sure where you stand today? An AI visibility audit checks all four pillars at once.
Frequently asked questions
Do AI crawlers run JavaScript?
Most don’t. Vercel found that none of the major AI crawlers it measured render JavaScript, including OpenAI’s and Anthropic’s. Gemini is the exception, because it uses Googlebot’s rendering infrastructure.
Do I need llms.txt to appear in AI answers?
No. Google says you don’t need AI text files or special markup for AI Overviews or AI Mode. llms.txt is an optional proposal; readable HTML, structure and schema come first.
Can I block AI training but stay visible in ChatGPT search?
Yes. OpenAI uses GPTBot for training and OAI-SearchBot for search, and each robots.txt setting is independent. Disallow GPTBot and keep OAI-SearchBot allowed.
What’s the next step?
The technical setup isn’t the goal.
It’s the difference between existing or not existing for an AI engine.
Want to know whether AI engines can read and cite your current site, and what that means for your requests? Contact us and we’ll start with a look at your raw HTML.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.