
Website & Development
AI-ready website checklist: 25 technical points before launch

Copy for AI
An AI-ready website lets AI crawlers fetch, read and understand every page cleanly.
It isn’t a visual trick.
It’s a list of concrete build decisions: how you render, what you put in the HTML, which crawlers you allow and how fast you load.
The verdict: if a bot can’t read your raw HTML, no GEO strategy will save you. Fix the build first, then the content.
This page is the technical launch checklist. It has 25 points a developer works through before taking a B2B site live.
Scope: the build and the technology, not your editorial GEO strategy. The two are complementary: without clean technology, no model will ever read your best content.
Quick check: run your homepage through our free AI visibility checker before you start.
Why is the technical side decisive for AI findability?
Because an AI model can only cite what it can cleanly fetch and parse.
Tools like ChatGPT, Perplexity and Google’s AI overviews send crawlers to your site.
They fetch the HTML and try to work out what your page is about.
Two things knock you out before your content is ever assessed:
- the fetch fails, because of a block or an error
- the bot receives an empty page that only gets built in the browser with JavaScript
In other words, the technology is the gateway: it decides whether you’re in the running at all.
Our experience: in the log file analyses we run for larger companies, the number of AI agents visiting websites grows significantly year over year. The gateway gets busier every year.
A dev handover document, not a content plan
That makes this checklist a dev handover document. Keep it apart from the editorial choices in your GEO strategy:
- which topics you cover
- which answers you give
- which authority you build
The one question: are the foundations technically sound at handover?
For the wider build process and the choices around it, see our guide to having a B2B website built.
The 25 points split into four groups:
Work through them in that order. A blocked or empty page makes everything after it irrelevant.
Which points cover rendering and crawl access?
The most important rule: make sure your content is already in the first HTML response, not only after JavaScript has run.
Many AI crawlers render JavaScript only partially or not at all.
So anything that appears client-side only doesn’t exist for them.
1. Server-side rendering or pre-rendering
Deliver the core content in the initial HTML, via SSR, static generation or pre-rendering.
For example, a purely client-side SPA whose text only appears after loading is risky for crawlers. Our explainer on server-side rendering for SEO compares the options.
2. Important text sits in the HTML source
Use “view source” to check that your headings, paragraphs and links are visible without the browser running scripts.
Test: right-click, View page source, then search for a sentence from your main heading. No match means a crawler may not see it either.
3. A correct robots.txt
Don’t block folders or resources crawlers need. And do allow the AI crawlers you want to give visibility to. Our AI visibility audit shows how to check each search bot separately.
It can be very short. This is ours:
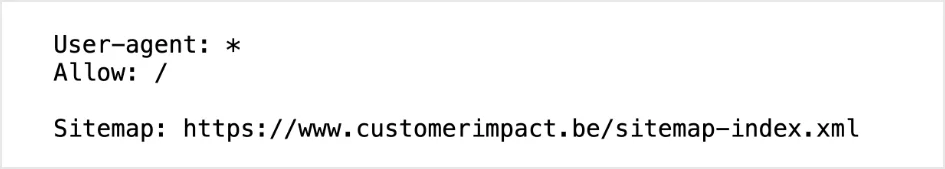 Our own robots.txt, October 2026: one rule for all crawlers, so every AI bot, training and search, may read the site.
One rule for every user agent, plus the sitemap line. Add a separate user-agent line only for a bot you deliberately want to block.
4. A deliberate choice per AI crawler
User agents such as GPTBot and OAI-SearchBot (OpenAI), ClaudeBot (Anthropic) and PerplexityBot can be allowed or blocked individually.
Know what each one does:
- GPTBot: collects training data, per OpenAI’s crawler docs
- OAI-SearchBot: sites that block it won’t be shown in ChatGPT search answers
- Google-Extended: not a separate crawler but a robots.txt token
Per Google’s crawler overview, Google-Extended only controls Gemini training and grounding. It doesn’t affect your inclusion in Google Search.
Watch out: if you want to appear in AI answers, don’t accidentally block the bots you need for that. Our guides to allowing AI crawlers and blocking AI bots in robots.txt cover both sides.
5. An up-to-date XML sitemap
Generate it automatically and keep it clean: only indexable, canonical URLs.
Then reference it in robots.txt, as in the screenshot above. Here’s how to create an XML sitemap step by step.
6. No unintended noindex or crawl blocks
A forgotten noindex tag, or a staging block that travels along to production, is a classic at launch.
Check every template, not just the homepage. Our explainer on the meta robots tag shows where to look.
7. Correct HTTP status codes
Each type of page needs its own code:
- Live pages: 200
- Removed pages: 410 or 404
- Moved pages: a 301
Soft 404s (a 200 on an empty page) confuse crawlers.
After launch, Search Console shows how bots actually hit your status codes:
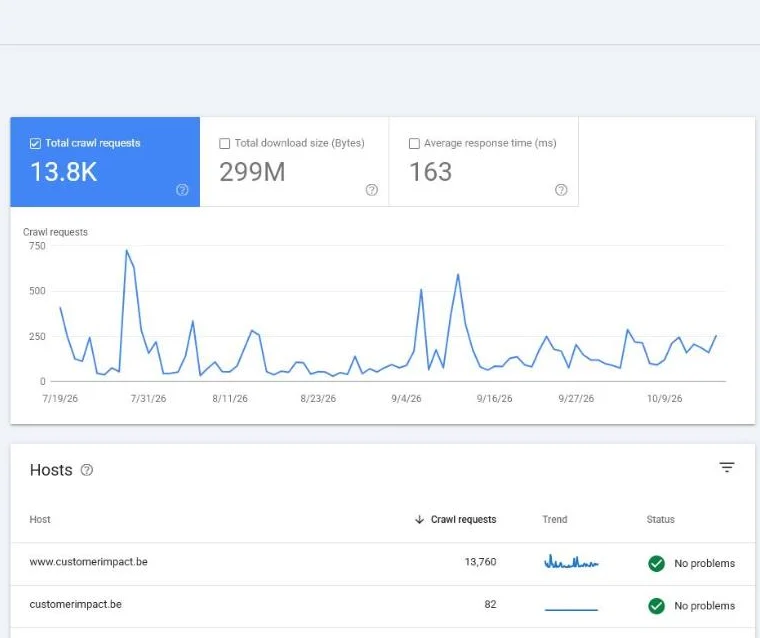 Crawl Stats in our own Search Console for customerimpact.be, October 2026. The breakdown by response shows how many requests hit a 301 or a 404.
A rising share of 404s or 5xx responses after launch points at a template or redirect error. Our guide to crawl stats in Search Console explains each column.
How do you make the structure machine-readable?
By using semantic HTML that makes the meaning of every element explicit, not just its styling.
A model infers your page structure from your markup. So the clearer that markup is, the better it can parse your content.
8. One logical H1 per page
The H1 names the main question or the main topic. One per page, no more.
9. A tidy heading hierarchy
H2s and H3s follow each other logically, without skipping levels.
Tip: phrase them as the questions a reader or an AI would ask.
10. Semantic elements
Use header, nav, main, article, section and footer instead of a sea of generic divs.
They tell a parser where the content sits and where the menus and footers start.
11. Descriptive, unique title tags and meta descriptions
Every page gets its own title and description that honestly summarise the content.
Duplicates across templates are a common launch bug. Check them in a crawl.
12. Alt text on meaningful images
It serves both accessibility and machine readability.
Also read our most common accessibility mistakes.
13. Descriptive, stable URLs
Use readable paths instead of cryptic parameters.
Pair them with a well-considered website architecture in which related pages hang together logically.
14. Internal links with descriptive anchor text
They show crawlers how your pages relate to each other and which ones matter most.
For example, “our guide to schema markup” says far more than “read more”.
15. Answer-first pages
Put the direct answer at the top of a section and build out from there.
That makes a passage easier to cite. A model can lift one clean paragraph without the context around it.
Which structured data belongs on the list?
Structured data (schema.org markup in JSON-LD) tells machines explicitly what a piece of content is.
For example, it can mark up:
- an organisation
- an article
- a frequently asked question
- a product
It’s no guarantee of visibility. But it removes guesswork and helps models interpret your entities correctly.
16. Organization markup
Add your company name, logo, location and contact details, so your brand is recognisable as an entity.
17. Article or BlogPosting markup
Use it on knowledge articles, with author and publication date.
18. BreadcrumbList markup
It makes your site structure explicit, page by page.
19. FAQ or Q&A markup, where it’s real
Use it where you genuinely answer questions, not as a gimmick on every page.
Google stopped showing FAQ rich results in Search on May 7, 2026. What’s left: no visual SERP boost anymore. The markup is purely about machine readability.
Our guide to FAQPage schema covers when it still makes sense.
20. Valid JSON-LD
Validate every template with a schema validator before launch.
Here’s what the result looks like on our own English homepage:
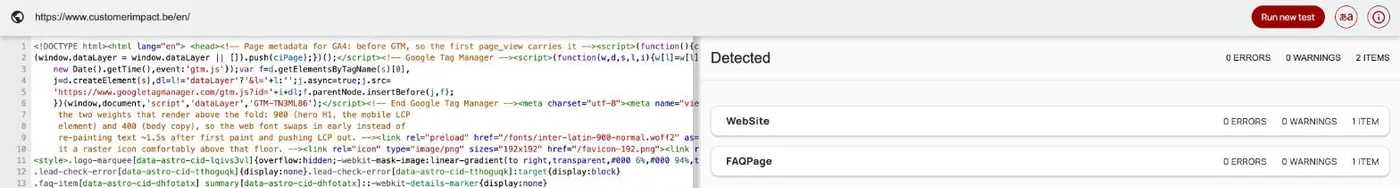 The Schema Markup Validator on our own English homepage, October 2026. Check that each detected type matches what the page visibly says.
Zero errors isn’t the whole test.
Each type should describe what a visitor actually sees on the page.
Dig into schema markup and the broader logic of structured data to pick the right types. Our walkthrough on schema markup testing covers the validators.
Which performance and technical points must be finished?
A fast, stable and secure site isn’t a luxury but a crawl condition.
Slow or error-prone pages get fetched less often and less deeply.
Bonus: performance also hits your conversion directly, because a slow site costs you leads before a human has read anything.
21. Good Core Web Vitals
Keep load speed, interactivity and visual stability within healthy margins.
Field data shows what real users get. This is ours on mobile:
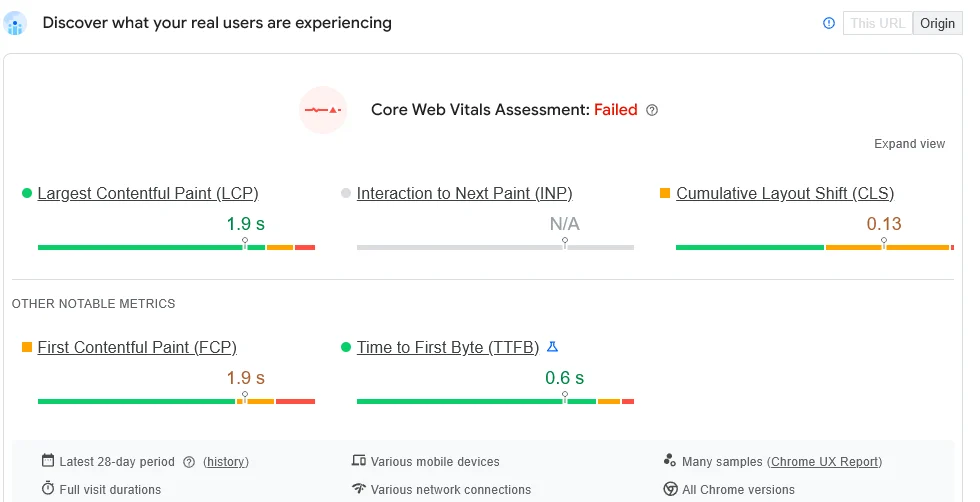 PageSpeed Insights field data for customerimpact.be on mobile, October 2026. LCP passes at 1.9 s; CLS at 0.13 still needs work.
One metric in the red is enough to fail the assessment, so check all three.
Our explanations of Core Web Vitals and Google Lighthouse help you measure. Or run a page through our website speed test.
22. Mobile-friendly and responsive
Crawlers generally assess the mobile version. That’s the version that counts.
23. HTTPS everywhere
Every page runs on HTTPS, without mixed-content warnings.
24. Canonical tags
They point duplicates and parameter variants to a single preferred URL.
25. Clean, consistent redirects
No chains or loops, certainly if you’re migrating from an old site.
And what about llms.txt, is it needed?
Optional, and with realistic expectations.
llms.txt is a proposed file in the root of your domain that points models to your most important content. Jeremy Howard published the proposal in September 2024.
What Google says about it
Google is explicit about its own AI features: you don’t need new machine-readable files, AI text files or special schema to appear in AI Overviews or AI Mode.
Our take: you lose little by adding it. But don’t count on it as a cornerstone. The gains sit in the 25 points above.
If you add one anyway, here’s how to create an llms.txt file.
Technology opens the door, content walks through it
Important to stay honest about: this checklist makes your site technically ready to be found, but guarantees no citations.
Whether a model picks you also depends on three things:
- your content
- your authority
- your relevance to the question
The technology opens the door, your content has to walk through it. We’d rather steer on that full chain than on isolated scorecards.
How do you check it works after launch?
Watch whether AI tools actually send visitors. In GA4 you can filter sessions on chatgpt.com:
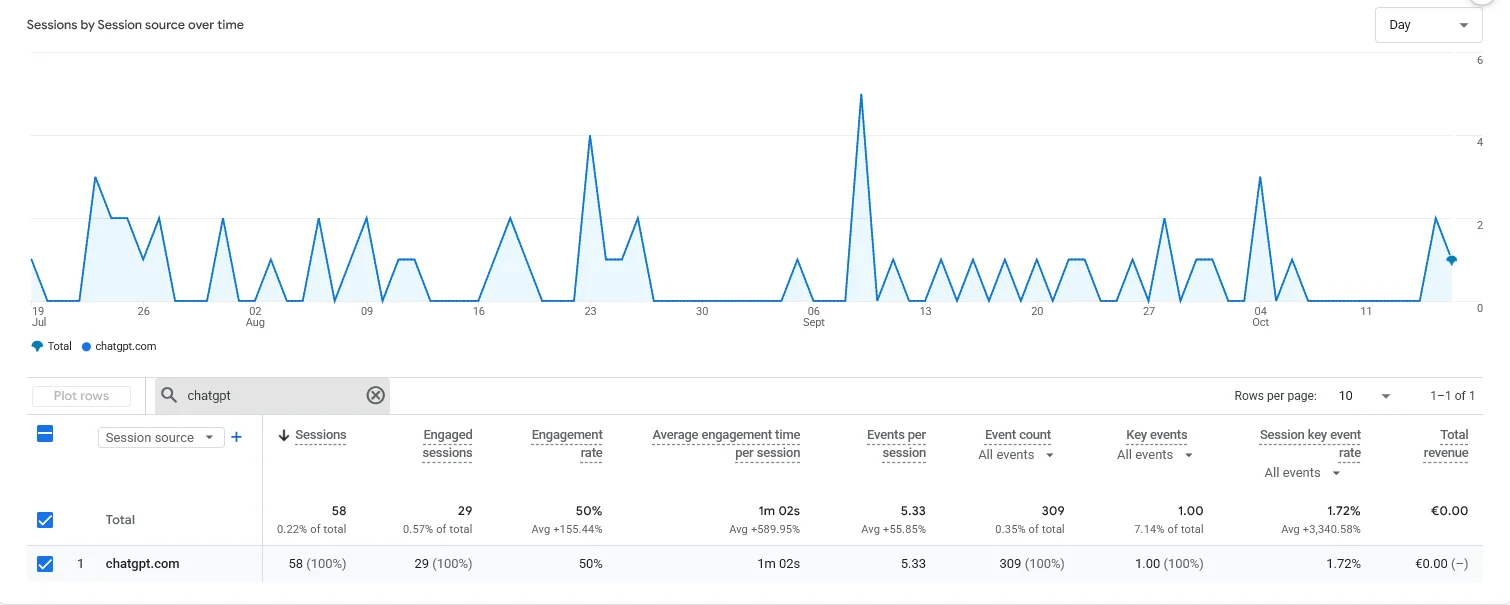 GA4 Traffic acquisition in our own property, last 90 days, October 2026: 58 sessions from chatgpt.com.
Small volumes. But a real signal. Here’s how to track ChatGPT traffic in GA4 yourself.
The short summary
An AI-ready website starts at the build.
Five things carry most of the weight:
- content in server-side HTML
- the right crawlers allowed in robots.txt
- semantic page structure
- valid schema markup
- clean performance and redirects
Work through these 25 points as a technical launch checklist. Keep it separate from your content strategy. Then you go live machine-readable.
Don’t forget: alongside the technology, also nail down what belongs in your website contract and SLA. That way handover, ownership and aftercare are locked down legally too.
Want an experienced team watching over these foundations with you? See how we can build your website or contact us.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.