
SEO & GEO
What Are Embeddings? The Marketing Explanation of Meaning Vectors

Copy for AI
Embeddings are how AI turns the meaning of a text into numbers.
They’re the key to how AI actually “reads”, and to why one page gets cited by ChatGPT or Google while another doesn’t.
The verdict: embeddings match content to questions on meaning, not on exact words. So you win AI visibility by covering a topic fully and clearly, not by repeating a keyword.
It sounds technical, but the idea is surprisingly simple. And it changes how you look at your content.
Below: what embeddings are, why they exist, and what they mean for you as a marketer who wants to be found in AI search engines.
What are embeddings exactly?
An embedding is a way of turning meaning into numbers.
An AI model can’t “understand” language the way a human does. It calculates.
So everything it processes first has to become something it can calculate with: a long string of numbers.
Vectors, in plain words
That string of numbers is called a vector. The vector that captures the meaning of a piece of text is the embedding.
OpenAI’s embeddings guide defines it just as plainly: “An embedding is a vector (list) of floating point numbers.”
Google’s machine learning course puts it the same way: “An embedding is a vector representation of data in embedding space.”
New to the models behind this? Start with what an LLM is.
Meaning, not words
The important word is meaning.
An embedding doesn’t record which words appear in a text. It records roughly what the text is about.
Take these two phrases:
- “an affordable car for the city”
- “a cheap vehicle for the daily commute”
They share almost no words, yet they mean something very similar. In the world of embeddings they end up close to each other.
The whole idea in one line
Texts with a similar meaning get similar vectors. Texts about different things end up far apart.
The model needs no dictionary to know “car” and “vehicle” are the same thing. It simply sees that their vectors sit close together.
Google’s course describes it the same way: “words that are used in similar contexts will be closer to each other in embedding space.”
Think of a map of meaning
Picture a gigantic map on which every concept gets a place.
Related things end up near one another. Here’s a simplified example of two neighbourhoods:
“Lead generation”, “booking appointments” and “sales conversations” form one neighbourhood. “Holidays”, “beaches” and “plane tickets” sit somewhere else entirely.
More directions than north and south
The difference with a real map: this one doesn’t have two directions but hundreds to thousands.
For example, OpenAI’s text-embedding-3-small model produces vectors with 1,536 dimensions by default. Text-embedding-3-large produces 3,072.
Each direction captures another fragment of meaning. You can’t picture it, and you don’t need to.
Rule of thumb: distance on that map equals difference in meaning.
In OpenAI’s words, “small distances suggest high relatedness and large distances suggest low relatedness.”
How a question finds its answer
When someone asks an AI a question, that question also becomes a point on the map.
Then three things happen:
- The question gets its own vector.
- The system looks for the content closest to that point.
- The closest pieces are the likeliest to be used in the answer.
So AI doesn’t search literally for your words. It looks at which meaning fits most closely.
You can see the result in Perplexity, which lists the pages it picked. Here’s the sources panel for one of our own test prompts:
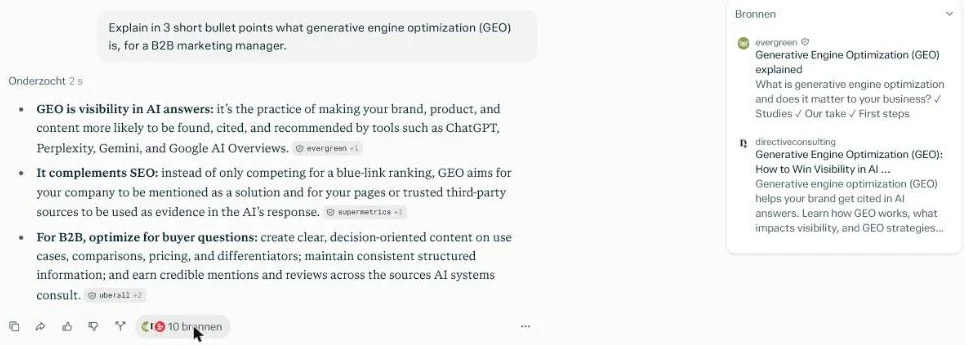 Perplexity’s sources panel for our own test prompt, 17 October 2026: 10 web pages behind one answer.
Retrieval systems mix more signals than embeddings alone.
But meaning-closeness gets a page onto that list.
Why this changes the entire logic of findability
The classic SEO reflex was: pick a keyword and repeat it.
If someone searched for “affordable company car”, that exact term had to appear on your page as often as possible.
Google moved past word matching years ago
Google describes how neural matching, introduced in 2018, “looks at an entire query or page rather than just keywords.”
Our explainer on semantic search covers that shift, and Google BERT is another step in it.
Repeating a keyword now works against you
Embeddings turn the old logic on its head. AI matches on meaning, so you gain nothing by repeating a term ten times.
Worse still: a page that forcibly repeats one keyword looks narrow in meaning space.
A page that really digs into the topic, with the natural variety of words a human uses, gets a richer, better-positioned vector.
From words to topics
So you no longer optimise for a word, but for a topic.
The question isn’t “how often does my keyword appear”. It’s “do I treat this topic so fully that my content sits close to every way someone might ask?”
That’s a fundamentally different way of writing. It explains why in-depth, well-structured content beats thin pages full of repetition.
You can see those many ways of asking in Search Console. Here are the real queries one of our niche pages gets found on:
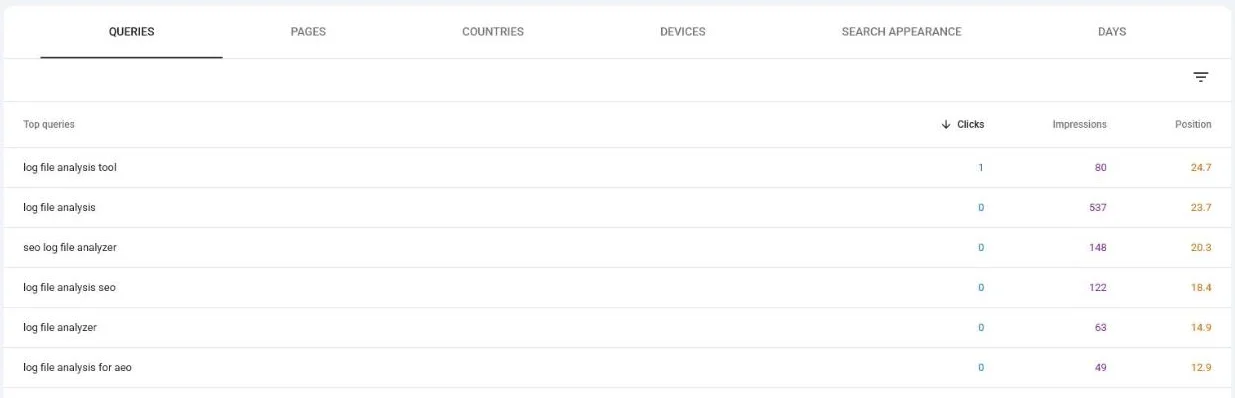 Queries for one page in our own Search Console, October 2026. Real searches, with impressions, for a niche B2B topic.
Different wording, same meaning, same page. That’s the pattern embeddings reward.
The broader framework is in our complete guide to generative engine optimization.
That’s why we insist on topic coverage, not keyword density.
What embeddings mean for your content
Once you know AI judges content on meaning, four practical consequences follow.
1. Write around the full topic, not one term
Cover the variants, the related questions and the context a reader logically expects, such as costs, risks and alternatives.
The more completely you cover a theme, the more ways of asking land “close enough” to be chosen.
A topical map helps you see which subtopics are still missing.
2. Use natural language
Synonyms, related concepts and your customers’ own words strengthen your position in meaning space. For example, write “vehicle” where it reads better than “car”.
You don’t need to fear “missing” a keyword if you phrase it differently. The model recognises the meaning.
Our guide to semantic keywords shows how to find those related terms.
3. Be explicit and concrete
Vague, general text gets a vague vector that isn’t really close to anything.
Specific, clear explanation gets a sharp position. It’s more easily matched to a specific question.
That’s one reason clear content performs better in AI answers.
4. Structure per question
Answer engines like to pick up a defined chunk that fully answers one question.
A clear heading with a complete answer beneath it is a neat, well-positioned block in meaning space. It’s easy to select.
Watch out: one section that tries to answer five questions ends up close to none of them.
Good for AI is good for humans
Embeddings reward clarity, completeness and honesty about your topic.
Tricks no longer work. The model looks past the words to the meaning.
How embeddings fit into the bigger AI search picture
Embeddings are one cog in a larger whole.
They decide how content and questions are matched on meaning. Whether your content ends up in an AI answer depends on more:
- whether the model retrieves live sources
- how it weighs authority
- how easy your text is to cite
We cover those mechanisms separately, so this article stays on the meaning vectors themselves.
The retrieval step is explained in what RAG is. The way one question splits into many searches is in our guide to query fan-out.
If you want your brand visible in ChatGPT, Google AI Overviews and Perplexity, that’s the work of our GEO service for AI search engines.
We turn this principle into more AI mentions, and then into leads.
The short summary
Embeddings are how AI turns meaning into numbers. That lets it compare texts on what they mean, not on which words they contain.
Picture a map where related concepts sit close together. A question becomes a point on it, and the model picks the nearest content.
The lesson: stop optimising for isolated keywords. Cover your topic fully, clearly and honestly.
Curious how your brand shows up in AI answers today? Run a free check with our GEO checker.
Want to know where you’re leaving AI visibility on the table? Get in touch with us and we’ll map your opportunities with you.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.