
SEO & GEO
What is a vector database?

Copy for AI
A vector database is storage where AI systems keep embeddings and search them by meaning.
Embeddings are meaning vectors: long strings of numbers that capture what a text is about. A vector database searches them by meaning rather than by exact words.
The verdict: a vector database is where an AI search engine finds, at lightning speed, which pieces of content most closely match a question. You don’t manage it, but your content ends up in it.
That’s why this piece of infrastructure completes the picture of how AI finds and cites your content.
What is a vector database, exactly?
A vector database is a database built to store vectors and search them by similarity.
An ordinary database is made to retrieve exact values, such as a customer number, a date or a price.
You look something up and get the row that literally matches.
How it differs from an ordinary database
A vector database works differently. It stores long strings of numbers, the embeddings.
For a given vector, it finds which other vectors lie closest to it.
| Ordinary database | Vector database | |
|---|---|---|
| Stores | Exact values (numbers, text, dates) | Embeddings (strings of numbers) |
| Searches by | Literal match | Similarity in meaning |
| Typical question | ”Give me customer 1042" | "Which fragments resemble this question?” |
| Result | The row that matches exactly | The nearest neighbours in meaning |
Where embeddings come from
That difference is fundamental.
Embeddings turn the meaning of a piece of text into such a string of numbers. Texts that mean something similar get similar vectors.
Exactly how that works, we explain in our article on what embeddings are.
A vector database is simply the storage that can handle this kind of meaning vector and search through it efficiently.
How does searching in a vector database work?
Searching in a vector database is all about distance.
The system turns your question into a vector. Then it looks for the stored vectors that lie closest to it.
That’s called a nearest neighbor search: looking for the “nearest neighbours” in meaning.
The pieces of content closest to your question are probably the most relevant to answer with.
The principle on its own is covered in what vector search is.
How distance is measured
“Close” needs a yardstick. Vector databases calculate it with mathematical distance functions.
The open-source pgvector extension supports six of them, according to its project page:
- L2 distance: the straight line between two points
- Inner product: how strongly two vectors point the same way
- Cosine distance: the angle between two vectors, popular for text
- L1, Hamming and Jaccard: for specific and binary vectors
For text embeddings you’ll meet cosine distance most often. You don’t need that maths to write good content.
The problem: scale
A large collection can contain millions or even billions of vectors.
Calculating the exact distance to every stored vector for every question would be far too slow. Answers need to arrive in a fraction of a second.
Exact search does exist. Pgvector does it by default and says it gives “perfect recall”: it’s guaranteed to find the best match.
But at scale, you choose speed.
The fix: approximate nearest neighbor (ANN)
That’s why vector databases use a smarter approach called approximate nearest neighbor, often shortened to ANN.
The word approximate is the crux. The system doesn’t guarantee the very best match, but a few neighbours that almost certainly belong among the best.
And it does so much faster. Pinecone frames it as a trade-off between accuracy and speed, where “a good system can provide ultra-fast search with near-perfect accuracy”.
The index: a smart map over the vectors
To pull that off, vector databases build a kind of index or smart map structure over the vectors.
A widely used technique, HNSW (Hierarchical Navigable Small World graphs), arranges the vectors in a layered network of connections. Malkov and Yashunin described it in 2016.
Sparse long-range links sit at the top, dense short-range links at the bottom.
The search starts at the top and zooms in layer by layer. So the system jumps quickly to the right neighbourhood instead of walking through everything.
Pgvector offers two index types:
- HNSW: a better speed-recall trade-off, but slower to build and heavier on memory
- IVFFlat: groups vectors into lists, faster to build, slower to query
The result is that a search finishes in milliseconds, even across a huge collection.
Watch out: the price is a tiny inaccuracy. In practice it’s well within acceptable limits.
Why is a vector database important for AI search engines?
Because it’s often the engine behind pulling sources into AI answers.
Many AI search engines don’t invent their answer from the model alone. They first retrieve relevant pieces of content and use them to support their answer.
That retrieve-and-generate pattern is called retrieval-augmented generation, shortened to RAG.
In the original RAG paper by Lewis et al. from 2020, the knowledge source was literally “a dense vector index of Wikipedia” searched by a neural retriever.
Retrieval in today’s systems typically still runs through meaning search in a vector database. The pattern itself is explained in what RAG is.
The flow in four steps
The flow always follows the same principle:
Whether your content ends up in that selection depends on how well your piece matches, in meaning, the way people ask questions.
Fragments, not complete pages
This explains why an AI system doesn’t cite your whole website, but exactly that one defined piece that fully covers a question.
The vector database works at the level of fragments. How to split content into such pieces is in content chunking for AI.
A clear heading with a complete answer underneath is precisely the kind of chunk that’s easy to find and select.
That’s why question headings work so well.
You can see that principle on the surface in Perplexity. Look at the source chip after each bullet:
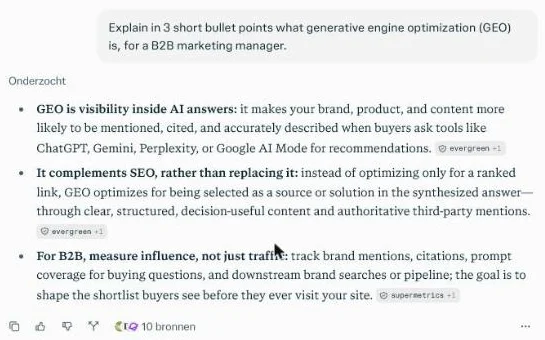 Perplexity free, logged out, 17 October 2026: a source chip on every bullet and 10 sources in total. The interface labels are in Dutch because we ran it from Belgium.
Each bullet leans on a different fragment, 10 sources for one short answer in our test. One click further, you see every retrieved page:
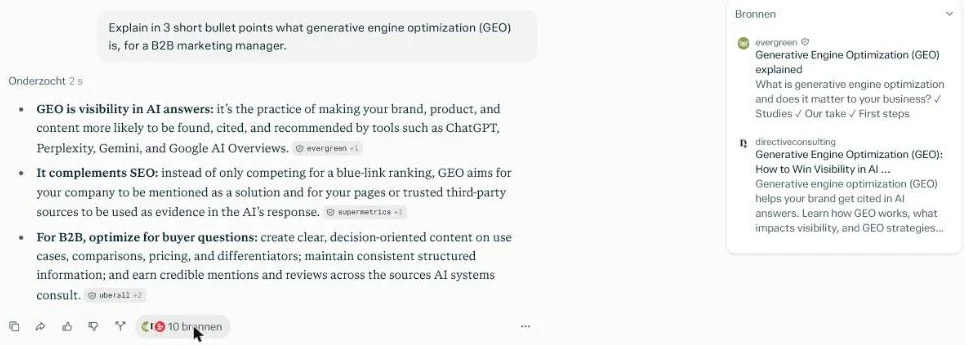 The 10 sources behind Perplexity’s answer, one click from the footer, 17 October 2026.
How to land in that list is in our guide to Perplexity SEO.
Meaning search is one link
Important to realise: meaning search is one link, not the whole story.
Whether an AI pulls live sources, and how it determines what’s correct and reliable, is a separate mechanism.
We cover that in our article on grounding, how AI determines what is true.
The question itself is sometimes split into sub-questions first. That’s called query fan-out.
Do I manage a vector database myself?
For most companies: no.
You don’t manage an AI search engine’s vector database yourself. But your content is the material that ends up in it.
When a system like ChatGPT, Google AI Overviews or Perplexity retrieves sources, that happens in infrastructure you don’t have your hands on.
What you do control
What you do have your hands on is how findable and selectable your content is.
Because retrieval happens by meaning, you gain nothing from repeating a keyword. You gain everything from covering your topic fully and clearly.
Content that covers a theme sharply and completely gets a better position in meaning space. It’s retrieved more often as a relevant fragment.
In concrete terms:
- One question per section: a heading and a direct, complete answer under it.
- Full context: the fragment must also make sense away from the page.
- Clear terms: define jargon inside the sentence itself.
How to write like that is in how to write content AI cites. The language models behind it are explained in what an LLM is.
A vector database for your own tools
For some companies, a vector database can also become a tool of their own.
For example, behind an internal knowledge base or a smart search function on their own site. Ready-made solutions exist:
- pgvector: a PostgreSQL extension that stores vectors next to your normal data
- Pinecone: a specialised, managed vector service
- Weaviate: an open-source vector database
But for the question of whether you get found in public AI search engines, that’s a side track. There, your content itself counts most.
How we look at it
At Customer Impact we don’t look at tricks to manipulate an index.
We look at whether your content passes the meaning test.
Does it cover the topic so completely that, for every logical question, it lies close enough to be retrieved?
That’s honest work that translates into AI mentions. And ultimately into leads and revenue, not vanity metrics.
How does the vector database fit into the bigger GEO picture?
The vector database is the storage and retrieval piece in the chain that decides whether AI shows your brand.
The chain in four cogs:
- Embeddings: turn meaning into numbers.
- Vector database: stores and searches those numbers.
- Grounding: decides what’s reliable enough to lean on.
- Language model: turns it into an answer.
Whoever understands these cogs sees why clear, well-structured content beats thin pages full of repetition. The related principle is in what semantic search is.
You’ll find the whole broader framework in our complete guide to generative engine optimization.
Frequently asked questions
What is the difference between a vector database and an ordinary database?
An ordinary database retrieves exact values, such as a customer number or a date. A vector database stores embeddings and returns the entries closest in meaning to your question.
Is a vector database the same as vector search?
No. Vector search is the technique of finding the nearest vectors. The vector database is the storage and index that makes that search fast at scale.
Can I influence how an AI search engine’s vector database ranks me?
Not directly. You can make your content clear, complete and well structured, so its fragments lie close to the questions people ask.
The short summary
A vector database is storage where AI systems keep embeddings and search them by meaning rather than by exact words.
It uses smart indexing, such as HNSW, to find within milliseconds the fragments that lie closest to a question.
That retrieval is often the engine behind the sources in an AI answer.
You usually don’t manage that database yourself. But the clarity and completeness of your content decide whether you get found.
Our GEO service for AI search engines translates these principles into a concrete approach.
Want to know where you’re leaving visibility on the table? Contact us and we’ll map your biggest opportunities first.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.