
SEO & GEO
What Is a Large Language Model (LLM)? Meaning for Marketers

Copy for AI
A large language model (LLM) is AI that writes by predicting the next word.
It’s trained on enormous amounts of text, and it builds every answer by constantly predicting which piece of text logically comes next.
It’s the technology behind tools like ChatGPT, Google Gemini, Microsoft Copilot and Perplexity.
The verdict: an LLM is a probability machine for language, not a fact database. That’s exactly why clear, consistent content decides whether it mentions your brand.
Below: the LLM meaning, how it answers, where it fails, and why that matters for your visibility in AI search.
LLM meaning: what is a large language model actually?
It’s a computer program that processes and generates human language.
It learned by recognizing patterns in an enormous collection of text.
What the three words mean
The three words actually say it all:
- Large: the scale. Both the training text and the model itself are gigantic.
- Language: it works with words and sentences, not with numbers in a database.
- Model: a mathematical system that learned patterns and applies them to new questions.
Not a search engine with an archive
Important to remember: an LLM isn’t a search engine with a ready-made archive of answers.
It doesn’t contain a list of facts that it looks up.
During training, it learned how language is put together.
Which words and ideas belong together, and which sentence usually follows which.
On that basis, it rebuilds every answer on the spot.
For example, say you ask a model without web access when your company was founded. It doesn’t retrieve a record. It writes the year that seems most likely from what it saw in training.
How does an LLM arrive at an answer?
It builds the answer piece by piece, each time calculating which next piece of text is most likely.
That happens in roughly three steps.
Step 1: your question becomes tokens
First, your question is cut into small pieces of text called “tokens”.
Per Google’s machine learning crash course, a token can be a word, part of a word or even a single character.
For English, Google puts one token at about 4 characters, or 3/4 of a word.
So 400 tokens are roughly 300 English words.
Our explainer on the AI token goes deeper.
Step 2: the model calculates probabilities
Next, the model looks at that series of tokens.
It calculates a probability for every possible next piece of text.
Google’s course uses a neat example.
For the sentence “When I hear rain on my roof, I _______ in my kitchen”, a model scores possible completions like this:
Even the winner only gets 9.4%.
The model doesn’t “know” the answer.
It weighs options.
Step 3: pick, attach, repeat
The model picks one, attaches it to the sentence, and repeats the exercise.
Token by token, word by word, the whole answer takes shape.
That’s why a chatbot often shows text appearing word by word: it’s literally being calculated at that moment.
Patterns, not guesswork
Those predictions aren’t guesswork. During training, the model saw patterns billions of times and learned which words fit together in which context.
It doesn’t calculate a human’s intent.
It calculates statistics about language.
A handy way to see how AI handles meaning rather than isolated words is our explainer on what embeddings are.
How is an LLM trained?
By reading enormous amounts of text and predicting the next word, over and over, while correcting its mistakes.
Guess the missing word, billions of times
Picture a learning process where the model gets a sentence with the last word left out.
It has to guess what goes there.
If it’s right, the approach stays.
If it’s wrong, the internal settings shift a touch.
Do that an unimaginable number of times on an unimaginably large pile of text.
The model gradually gets better at judging language.
The settings it adjusts live in a neural network, the core of deep learning.
From foundation model to assistant
That first phase gives you a so-called foundation model.
Chat assistants then get a second round: fine-tuning on task-specific examples.
It teaches them to follow instructions and answer like an assistant.
Where the training text comes from
That training text comes largely from the public internet: articles, websites, forums, reference works and more.
Two things follow from that:
- A cut-off point: a model is trained up to a certain moment and doesn’t know later events on its own.
- The gaps of the web: it learns from what’s online, including the gaps and biases in it.
What’s well and consistently described, it learns well.
What’s barely or contradictorily described, it knows poorly.
And that last point is exactly where you, as a brand, have influence.
What is an LLM good at, and what not?
It’s excellent at language and weak at factual certainty.
That distinction decides how you use it.
Strong: the form of language
An LLM is strong in everything to do with the form of language:
- summarizing and rewriting
- translating and adjusting tone
- generating ideas
- making long texts understandable
For that kind of work, it’s a powerful assistant.
Weak: the facts
Because a model builds the most likely answer and doesn’t look up truth, it can invent something plausible but wrong.
With full conviction.
That’s called “hallucination”: output that sounds plausible but is factually wrong or fabricated, as IBM puts it.
The model doesn’t lie on purpose.
It follows the most likely language pattern, even when that doesn’t match reality.
Our explainer on AI hallucination covers the causes.
Same question, different answers
You can see the probability at work by asking several LLMs the same question.
We gave ChatGPT, Claude and Gemini one identical GEO prompt.
Look at how the length and structure differ:
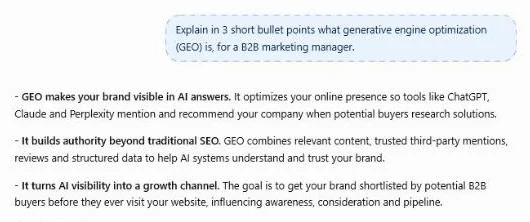 ChatGPT free (temporary chat), 17 October 2026: three bullets, about 90 words, no sources.
Claude answered the same prompt in a different shape:
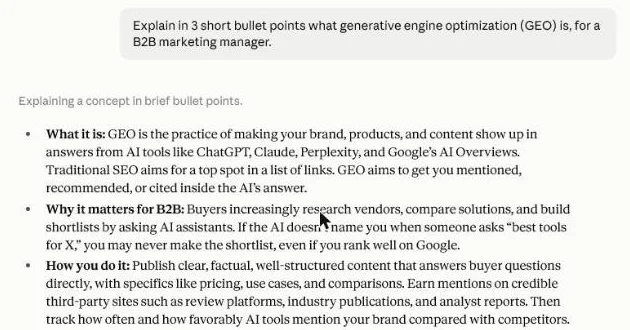 Claude, 17 October 2026, tested on a paid plan in an incognito chat: three labelled bullets, about 150 words, no sources.
And Gemini took yet another route:
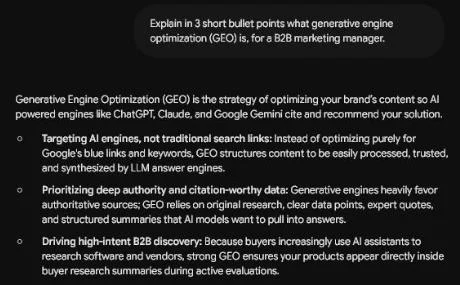 Gemini (Google Workspace account, Flash model), 17 October 2026: an intro sentence plus three bullets, about 120 words.
About 90, 150 and 120 words for one question.
Each model built its own answer from its own probabilities.
Our comparison of ChatGPT vs Claude vs Gemini goes into the differences.
How grounding softens the weakness
Many modern AI tools soften this by letting the model consult current sources while answering, rather than leaning only on memory.
How that process of linking sources to an answer works, you’ll find in our explainer on grounding: how AI determines what is true.
Perplexity shows it openly. Here’s the sources panel behind one answer in our own test:
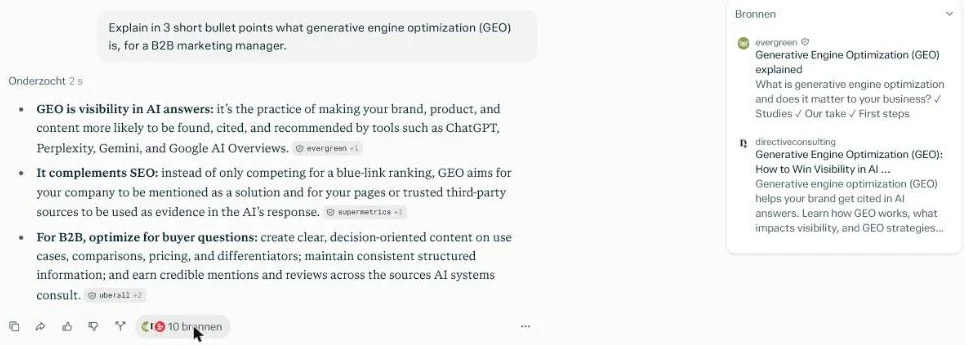 Perplexity’s sources panel for our own test prompt, 17 October 2026: 10 web pages behind one answer.
That’s also the bridge to why this concerns you as a marketer.
Why is an LLM relevant to you as a marketer?
Because more and more people ask an AI instead of a search engine.
And that AI decides which brands end up in the answer.
You used to fight for a spot in a list of blue links.
Now it’s about whether your company is mentioned at all in the answer the AI writes itself.
For example, say a buyer asks ChatGPT for IT service providers in Antwerp. The answer names a handful of companies, and everyone else is invisible in that moment.
Clear content gets reused, vague content gets ignored
This is where everything comes together.
An LLM builds answers from patterns it saw in text, and it increasingly leans on sources it retrieves on the spot.
Content that’s clear, consistent and well structured is easier for a model to understand and reuse.
Content that’s thin, vague or contradictory gets ignored.
Our experience: a clear positioning comes first. If you can’t tell your own story, the model fills the gap and starts to hallucinate about you.
GEO and LLMO
Optimizing your visibility in these AI answers is called GEO.
You can read all about it in our complete guide to generative engine optimization.
Tailoring your content specifically to language models is also called LLMO.
What LLMO (large language model optimization) entails, you can read separately.
Tip: check how ready one of your pages is with our free GEO checker. Then read how ChatGPT uses a search index to see where your page enters the process.
What we measure
At Customer Impact we don’t look at vanity metrics for this.
We look at what it delivers: are you mentioned when a potential B2B customer asks an AI a buying question?
That’s not a matter of tricks, but of reliable, findable content that a model is happy to cite.
Want to know whether your company shows up in AI answers today?
See how we work on visibility in AI search engines.
Frequently asked questions
What does LLM stand for?
LLM stands for large language model: an AI system trained on enormous amounts of text that generates language by predicting the next piece of text.
Is ChatGPT an LLM?
ChatGPT is a chat product built on large language models from OpenAI. The LLM generates the text; the product adds things like a chat interface and, in some modes, web search.
Why does an LLM make mistakes?
Because it predicts the most likely text instead of looking up facts. When the most likely pattern doesn’t match reality, it produces a confident but wrong answer, called a hallucination.
What is the difference between an LLM and a small language model?
Mostly size. A small language model has far fewer parameters, so it runs cheaper and can run locally, but it handles broad questions less well.
The short summary
A large language model is AI trained on enormous amounts of text.
It builds answers by repeatedly predicting the most likely next piece of text.
It understands nothing the way a human does.
It calculates probabilities about language.
That makes it strong at language work and weak at hard facts, because it can hallucinate convincingly.
Because these models power modern AI search, the clarity of your content decides whether your brand ends up in their answers.
Contact us and we’ll check which AI answers your company shows up in today, and where it’s missing.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.