
SEO & GEO
Primary bias: why AI models trust some brands by default

Copy for AI
Primary bias is an AI model’s baked-in preference for a brand, before it searches.
Ask ChatGPT two questions: “Which CRM should I pick for my enterprise?” and “Which supplier should I choose for customer feedback in the Benelux?”
On the first, a list of names rolls out instantly, full of confidence, without the model looking anything up.
On the second, it hesitates. Or it names companies that have nothing to do with you.
The verdict: that difference is primary bias. It decides whether AI names you when it doesn’t search, and you build it over years, not weeks.
Below: how that preference forms, why it decides your AI visibility, and how to measure and build it.
Check your own page: get a GEO score with concrete tips through our free GEO check.
What exactly is primary bias?
A model’s inherent trust in an entity, before any retrieval or grounding takes place.
Call it the AI’s “gut feeling”: a worldview locked into the training data.
Four kinds of association
When a model meets your brand name, it doesn’t start from zero. It starts from the associations its training data have shaped.
Those fall roughly into four categories:
- Strong and accurate: well-known brands with clear positioning.
- Strong and wrong: brands tied to the wrong category, such as a software firm known for its old consulting arm.
- Weak: brands that barely appear in the training data.
- Absent: brands the model has never encountered.
What primary bias decides
Primary bias operates upfront, separate from the selection process that kicks in when a model searches live.
It determines four things:
- whether the model is inclined to mention your brand at all
- which attributes it attaches to you
- how confidently it talks about you
- whether your name surfaces on relevant questions
It’s literally a prejudice: a pre-judgement based on pattern recognition in historical data.
New to how models work? Start with what an LLM is.
How does primary bias form in the training data?
Through repeated associations in the text a model learns from.
Language models train on huge volumes of text: web pages, books, articles, forums and documentation.
What one published training mix looks like
OpenAI’s GPT-3 paper is one of the few that published its mix. Filtered Common Crawl made up 60% of training, WebText2 22%, two book corpora 8% each and Wikipedia 3%:
During that training, the model learns patterns of association.
If your brand name often appears next to certain concepts, products or attributes, the model learns that link.
Common Crawl is the big one
Common Crawl describes itself as a free, open repository of web crawl data with over 300 billion pages spanning 15 years.
So what the open web says about you matters a lot. Dig into the role of Common Crawl in your ChatGPT visibility to see which pages really count.
An established brand vs a newcomer
Take an established name like Salesforce.
The training data contain thousands of articles about Salesforce as a CRM: documentation, tutorials, news, forum threads and comparisons with competitors.
From that, the model learns strong associations: Salesforce equals CRM, equals enterprise, equals cloud computing.
Ask “Which CRM should I pick for enterprise?” and the model leans toward Salesforce before it looks anything up. That preference is baked in.
A newer company in the same market is in a different position. It may have excellent products and strong current content.
But if it launched after the training cutoff, or was rarely discussed in the corpus, its primary bias is weak or absent.
The model has no inclination toward it. It starts every interaction from zero and has to earn every mention through grounding.
How does primary bias differ from grounded knowledge?
Primary bias sits in the model’s weights; grounded knowledge comes from a live search.
The distinction is crucial for your strategy. They’re two different forces.
The two side by side
| Primary bias (parametric) | Grounded knowledge (retrieved) | |
|---|---|---|
| Where it comes from | Formed during training | Gathered in real time through a search |
| How stable | Fixed until the model is retrained | Changes along with your web content |
| When it applies | Every question about your brand | Only when grounding is triggered |
| Can you steer it | Not directly with content changes | Directly, through content optimization |
| Visibility it creates | Baseline, independent of current content | Depends on the quality of current content |
What it looks like in practice
Here’s an answer from the model’s own knowledge. ChatGPT answered without searching and cited nothing:
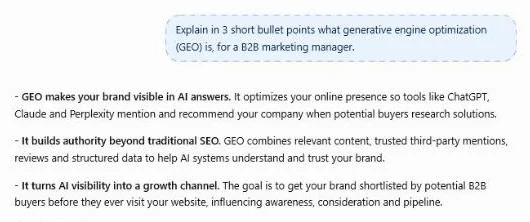 ChatGPT free (temporary chat), 17 October 2026: three bullets, about 90 words, no sources. Everything here comes from the model’s weights.
And here’s a grounded answer to the same prompt. Perplexity searched first and shows its sources:
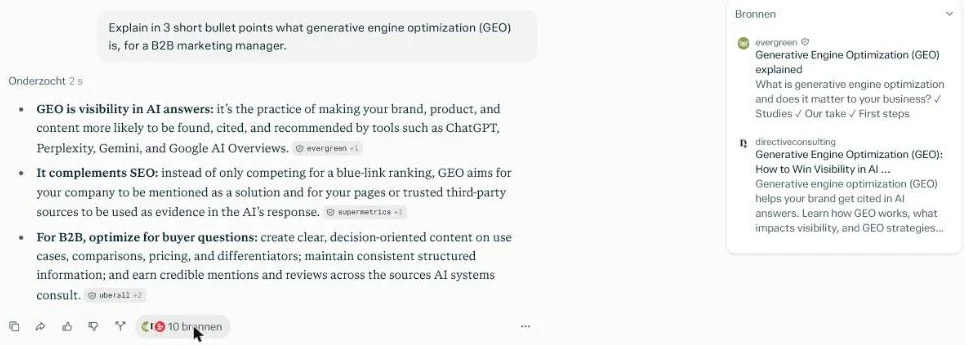 A Perplexity answer to a GEO prompt with its sources panel open, our own test in October 2026. Every bullet links back to the page it came from.
How the two forces play together
For questions that trigger a search, both forces play together. Primary bias sets an initial inclination; grounding reinforces or corrects it.
For questions that trigger no search, primary bias is all that counts.
The model then answers purely from its weights. Those reflect the training data, not your latest blog post.
Which prompts make a model search? See prompts that trigger ChatGPT search and how ChatGPT uses its search index.
Four strategic positions
That produces four positions:
| Primary bias | Content | Position |
|---|---|---|
| Strong | Strong | Dominant, hard to displace |
| Strong | Weak | Vulnerable, grounding can favour competitors |
| Weak | Strong | Opportunity, content has to work harder |
| Weak | Weak | Invisible, fundamental repositioning needed |
To understand how the grounding side works, the ultimate GEO guide goes deeper into the full playing field of generative engine optimization (GEO).
That side is measurable too. The GEO paper by Aggarwal and colleagues found that GEO “can boost visibility by up to 40%” in generative engine responses.
In short: grounding is the fast lever, primary bias the slow one.
How do you measure primary bias?
Through targeted testing, because primary bias isn’t directly visible.
Three approaches work well.
Completion tests
Give the model prompts without grounding and see what it generates.
For example: “When companies want to collect customer feedback, they often choose…” or “The leading providers in this market are…”.
Run such a prompt many times to absorb sampling variation, and count how often each brand shows up.
Rule of thumb: the more often your brand appears unprompted, the stronger your primary bias.
Association tests
Test what the model connects to your brand:
- “[Your brand] is known for…”
- “Companies use [your brand] when they…”
- “[Your brand] compared to competitors is…”
The completions reveal which associations sit in the model’s weights.
They may be accurate, outdated, incomplete or even completely wrong. But it’s what the model “believes” about you.
Watch out: a confident but wrong answer is close to an AI hallucination, and just as sticky.
Bidirectional testing
Test the association in both directions:
- Forward: “Best solutions for [category]”. Does your brand appear?
- Backward: “[Your brand]”. Which category does the model link it to?
Strong primary bias shows up in both directions.
With weak bias, the model may know your brand but fails to link it to the relevant category.
Measure across platforms
Google, OpenAI and Anthropic train on different data. So your primary bias can be strong on one model and weak on another.
A one-size-fits-all approach misses that nuance.
This logic closely matches how you measure brand salience for AI. In both cases you check whether, how often and in which context a model calls up your brand.
You can run these tests by hand. Our guide to measuring AI visibility without tools shows how, and which prompts to track helps you pick them.
What are the upside and the downside of strong primary bias?
Strong, accurate bias gives you a head start; very strong bias can also freeze an outdated picture.
Three structural advantages
Brands with a strong, accurate primary bias get three advantages:
- Baseline visibility: even with mediocre content, the model stays inclined to mention them.
- Selection preference: content gets evaluated more favourably during grounding.
- Compound effect: mentions create content, which strengthens the next training data.
The selection preference is a form of confirmation bias. If the model already leans toward you, it reads your pages more kindly.
The compound effect is a rich-get-richer dynamic.
It’s a self-reinforcing loop: the more visible a brand is today, the stronger its position in the next training round. And the harder it gets for newcomers to break in.
The cost of weak bias
Weak or absent primary bias creates the opposite:
- you start every question from zero
- you feel headwind during selection
- your visibility depends entirely on whether grounding gets triggered
And if you do get mentioned, it’s often with doubt: “I found a company that…” instead of a confident mention.
That uncertainty carries over into how the user sees you.
The paradox: very strong bias
Very strong primary bias can work against you.
If the model is highly convinced about an entity, it triggers a search less readily, because it “knows” the answer already.
The result: your carefully optimized current content doesn’t get retrieved. The model answers from possibly outdated training knowledge.
For well-known brands, that’s a challenge. How do you correct an outdated picture when the model is convinced it already knows you?
Two things help: time-bound phrasing that forces grounding, and content that explicitly contradicts the old picture.
For example, a prompt such as “which CRM is best in 2026” is that kind of time-bound phrasing.
How do you build primary bias?
With mentions in authoritative sources, and patience: it’s a long game.
If primary bias sits in the training data, can you influence it? Yes, in four ways.
1. Presence in training sources
Models train on authoritative, frequently crawled sources: Wikipedia, established news media, trade publications, academic work, popular forums.
Getting mentioned there, not just on your own site, builds presence in future training data.
Digital PR for AI citations is the most direct route. For a Wikipedia entry, see creating a Wikipedia page for your business.
2. Consistent entity association
Associations emerge through repetition, for example the same category phrase in every press mention.
If you’re consistently mentioned alongside your target concepts, that link strengthens. Scattered, inconsistent messaging creates confused associations instead.
Our guide to entity SEO covers how to make your brand one clear entity.
3. Authority signals
Not all training data carries equal weight.
The GPT-3 authors wrote that datasets they viewed as higher quality were sampled more frequently.
Wikipedia was seen 3.4 times during training, filtered Common Crawl less than once (0.44).
So a mention in a major outlet probably counts for more than dozens of mentions on obscure blogs.
4. Time horizon
Primary bias only changes at retraining. For large commercial models that happens periodically, with months to years in between.
Rule of thumb: think in years, not months, and build presence now for the next training rounds.
Why earned media matters
This logic explains why we put so much emphasis on earned media, in brand mentions vs backlinks and in brand mentions for SEO.
It’s precisely the mentions in authoritative sources that feed your primary bias over time.
Meanwhile, don’t neglect your grounded visibility. Optimize your content for the short term while you build for the long term.
Track both sides with your AI share of voice over time.
Frequently asked questions
What is the difference between primary bias and grounding?
Primary bias is a model’s fixed, baked-in knowledge about your brand, formed during training. Grounding is the live search with which a model retrieves current information at the moment of the question. Primary bias always applies, even without a search; grounding only plays a role when the model actually searches. Both count for your strategy, but you influence them in different ways.
Can a small or new brand build primary bias at all?
Yes, but it takes time and it does not happen through your own website. You build it by getting mentioned in authoritative external sources that count in future training rounds: trade media, press coverage, Wikipedia, expert roundups. Because models are only retrained periodically, you see no immediate result. In the meantime, you win visibility through strong, grounded content that wins the selection despite the headwind.
How do I know whether my primary bias is accurate or wrong?
Run association tests: ask the model what your brand is known for and when companies bring you in. Compare the answers with your own positioning. If the picture is right, you mainly need to reinforce it. If the model associates you with the wrong category or with outdated information, you need a correction strategy, and that is harder than starting from zero, because the model has to unlearn first.
Does my primary bias differ per AI platform?
Yes. ChatGPT, Gemini and Claude train on different data, with different cutoff dates and source weighting. You can score strongly on one model and weakly on another. That is why you always measure your position across multiple platforms, and tune your strategy per platform: lean on your strengths where you already have a head start, and invest in grounded visibility where you are lagging.
Need help?
Start by measuring where you stand. Our free AI visibility checker gives you a first read.
Want to translate this into execution? See how we approach this with AI visibility.
100 GEO tips to get named in ChatGPT and Google AI
- 10 chapters:from robots.txt and Bing to measurement
- Copy-paste:regex for Search Console and GA4
- Templates:buying questions per stage and a 30-day plan
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.