
SEO & GEO
Which prompts to track? Building a representative monitoring set

Copy for AI
Track the prompts your buyers actually ask AI, not the keywords with the highest volume.
The verdict: a useful monitoring set is a deliberate selection of buying questions. It’s spread across funnel stages, industries and regions, so you see whether AI mentions your brand at the moments that lead to revenue.
So which prompts to track? Below: how to build that set, how large it should be and how to maintain it.
This fits within our guide to Generative Engine Optimization.
GEO makes you visible in AI answers.
Your prompt set tells you whether you can measure that reliably.
What is a prompt set and why does it matter?
A prompt set is the fixed list of questions you periodically put to AI systems.
You use it to measure whether, how and in what context your brand is mentioned.
The AI version of a keyword list
It’s the AI equivalent of a keyword list in classic SEO, with one important difference.
A prompt is a full question in natural language, not a single term.
In ChatGPT or Perplexity, people don’t type “fleet management software”.
They ask “what is the best fleet management software for a transport company in Belgium”.
Our research on why ChatGPT queries are getting longer shows where that shift comes from.
The set is the yardstick
That set matters because it determines what you can see at all.
Measure the wrong questions and you get a reassuring or alarming report.
Either way, it says nothing about your real commercial position.
A brand can score brilliantly on broad informational questions.
Yet it can be completely invisible the moment a buyer asks for a concrete recommendation.
The point: the prompt set isn’t an administrative detail. It’s the yardstick itself.
Which prompts should you track?
Track the prompts where a buyer makes a choice, compares or asks for a recommendation.
That’s where your visibility turns into a lead.
So don’t start with search volume. Start with what your sales team hears every day.
Here’s what a recommendation answer looks like. We asked ChatGPT for the best tools to track AI citations:
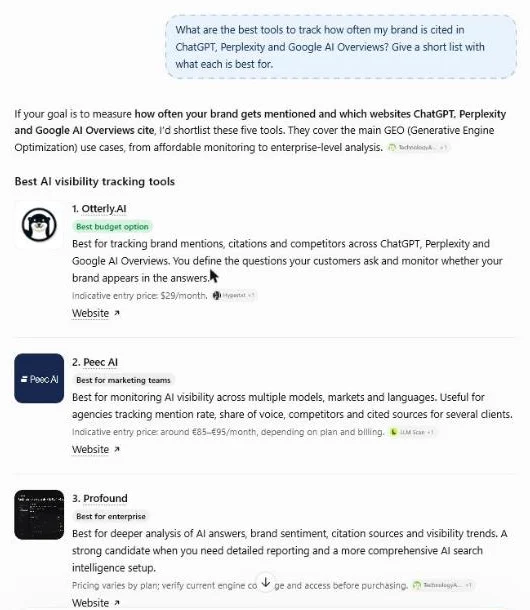 Our own ChatGPT test on 17 October 2026. Note who’s named, in which order and with which label.
One question, one shortlist.
Not on it? The buyer may never hear of you.
The four prompt types every set needs
Four types of prompts belong in every serious set:
- Category questions: “best [category] for [type of company]” or “which [solution] should I choose for [situation]”.
- Comparison questions: “[Brand A] vs [Brand B]” or “alternatives to [known player]”.
- Problem questions: “how do I solve [problem]”.
- Brand questions: “what does [your brand] do” or “is [your brand] reliable”.
What each type tells you
Each type answers a different question about your position:
| Prompt type | What you learn |
|---|---|
| Category | are you named at the recommendation moment? |
| Comparison | are you in the consideration set? |
| Problem | does AI put your approach forward as a solution direction? |
| Brand | does AI describe you correctly and consistently? |
Brand questions also show sentiment.
Our piece on AI brand mention sentiment covers how to read it.
The vanity trap
The biggest mistake is filling the set with general informational questions because they seem to have the most “volume”.
For example, “what is email marketing” produces a neat answer.
But it rarely names a brand. And it never brings a lead.
At Customer Impact we steer clients away from those vanity metrics.
We measure visibility on the questions buyers ask right before they get in touch, not on the questions that look busy in a report.
How do you distribute prompts across the funnel?
Spread your prompts deliberately across the three funnel stages, so you can see where your visibility drops off.
Many brands are perfectly visible at the top of the funnel.
They disappear precisely where the decision is made.
By measuring per stage, you make that gap visible instead of averaging it into a vague overall figure.
The three stages
Here’s how each stage fills up:
- TOFU (awareness): broad problem and how-to questions. Here you want to be cited as a source, not necessarily as a product.
- MOFU (consideration): category and comparison questions. This is the core of your set, because here AI decides whether you make the shortlist.
- BOFU (decision): concrete buying, pricing and provider questions, often with a region or industry. “Who can deliver [service] in [region]”.
A handful of TOFU prompts is enough. That’s rarely where you win or lose.
At BOFU, every mention counts.
A healthy distribution
For B2B, the centre of gravity deliberately lies with MOFU and BOFU, because that’s where buying decisions are made.
A healthy split is roughly a quarter of your prompts in TOFU, half in MOFU and a quarter in BOFU.
Adjust it to your own buying journey.
For example, say your set holds 40 prompts. The split then looks like this:
How to fill those stages in further, you can read in our take on GEO for B2B.
How do you account for industry and region?
Add industry, company type and region to your prompts explicitly.
AI answers vary strongly by context, and a generic question hides where you’re really strong or weak.
“Best accounting software” gives a different answer than “best accounting software for a sole trader in Flanders”.
Customers mainly from one sector or region? Then your set has to carry that context.
Swap one dimension at a time
Work with variants of the same core question. Swap out one dimension each time:
- the industry
- the company size
- the language
- the region
That way you see not only whether you’re mentioned, but also where your position falls away.
Language is a real risk in Belgium
A brand that scores well in Dutch may be unfindable in a French-language variant of the same question.
In Belgium, that’s a real risk.
Watch out: never assume one language’s result holds for the other.
This touches on how AI decides who’s relevant for which context, the subject of our five key indicators of AI visibility.
How large should your prompt set be?
As small as responsible and as large as necessary.
Better thirty to sixty sharp prompts that you follow consistently than hundreds of variants nobody still interprets.
The point of monitoring is to steer.
And you can only steer on a set you understand and check regularly.
Build a small cluster per theme
A workable approach is a small cluster per core theme:
- one category question
- one or two comparison variants
- one industry or region variant
With five to ten commercially relevant themes, you naturally land on a set that’s complete without becoming unmanageable.
Our experience: for a full baseline we go bigger, to around 100 non-branded middle and bottom-of-funnel questions.
Ten questions is too few to mean anything.
Consistency beats size
More important than the size is consistency: the same prompts, at fixed moments, so that shifts gain meaning.
Asking a hundred questions once is a snapshot, not monitoring.
Why repetition matters
Mind the practical side too.
AI answers vary between models and even between repeated questions.
Google says it plainly: AI Mode and AI Overviews may use different models and techniques, so the responses and links they show will vary.
How much do they vary? In a SparkToro study, 600 volunteers ran 12 prompts through ChatGPT, Claude and Google’s AI 2,961 times.
There was less than a 1 in 100 chance that ChatGPT or Google’s AI returned the same brand list twice in 100 runs.
The authors’ conclusion: visibility percentage across many repeated prompts is a reasonable metric.
A “ranking position” in AI isn’t.
Report mention rate, not position
So measure each prompt on multiple systems, with repetition.
Report how often you’re mentioned, not your position.
Our experience: prompt monitoring runs every few hours, because models drift.
For our own brand, Perplexity named Customer Impact in 16 of 125 agency-choice prompts, up from 7.
That’s the number a set should produce: a share of prompts, tracked over time.
Our guide to AI share of voice explains the metric.
The more prompts, the heavier repetition weighs on cost.
A compact set is clearer and cheaper to run.
Where the tools fit
Monitoring tools run your set for you and chart mention rate per competitor:
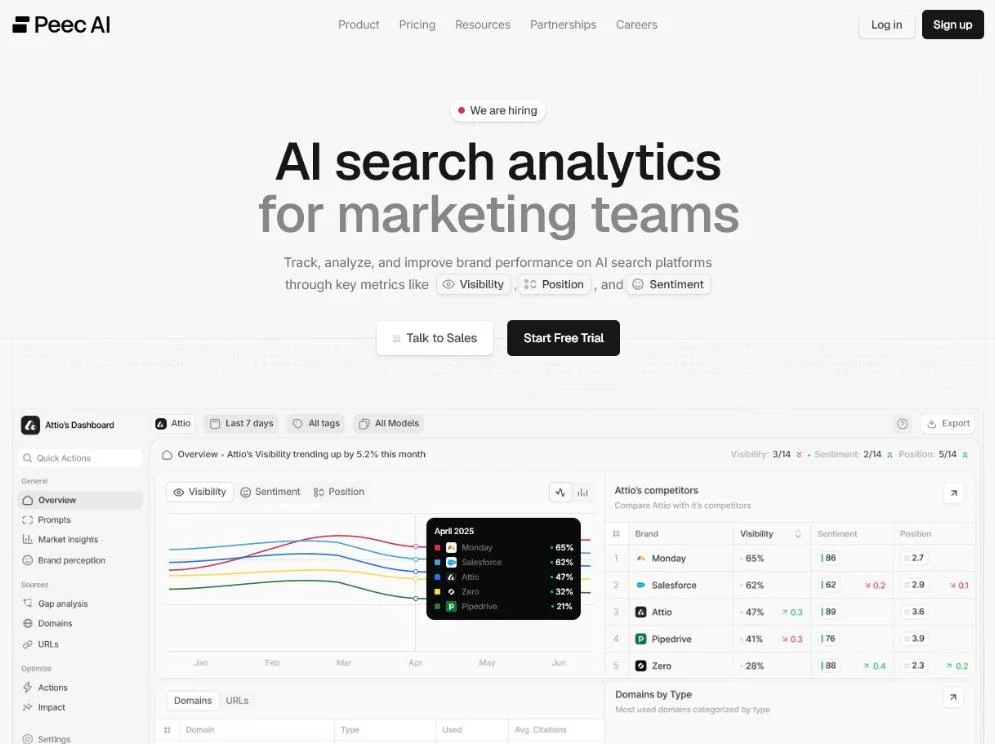 Peec AI’s homepage, October 2026. Visibility, sentiment and position sit next to each competitor.
The tool only measures what you feed it.
A weak prompt set gives a polished dashboard of the wrong questions.
We compare platforms and methods in our overview of AI visibility tools.
Tight budget? Start with measuring AI visibility without tools.
How do you maintain your prompt set?
Revise it every quarter, as a living document.
Buying behaviour and the way people query AI change faster than classic search habits.
Leave a set unchanged for a year and it slowly measures the wrong reality.
Three sources feed the revision
Three sources feed that revision:
- Your sales team: new objections and prospect questions are often new prompts.
- The AI answers themselves: the follow-up questions models suggest show how buyers think further.
- Your competitors: a new player in the comparison answers belongs in your comparison prompts.
Check the sources behind each answer
When you revise, also look at which pages an answer leans on. Perplexity shows them per answer:
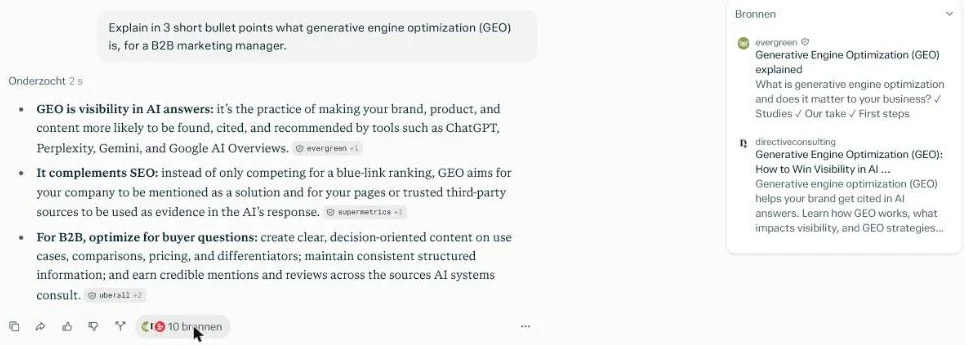 Perplexity’s sources panel for our own test prompt, 17 October 2026: 10 web pages behind one answer.
Perplexity says each answer includes numbered citations linking to the original sources.
Those pages show where to earn a mention.
Prune as well as add
Just as readily, remove prompts that no longer give a usable signal.
Rule of thumb: a sharp set stays sharp through pruning, not only through adding.
Want a quick first read before you build the full set? Our free AI visibility checker shows where you stand today.
Rather not learn the models yourself? Our service for AI visibility sets up the set and turns signals into actions.
The short summary
A good prompt set measures your real commercial position in AI answers, not your chances on broad informational questions.
Start from the questions buyers ask.
Spread them across funnel stages, industries and regions. Keep the set compact and revise it every quarter.
That way AI visibility becomes a steerable number instead of a reassuring report.
Contact us and we’ll build a prompt set with you that measures what matters for your business.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.