
SEO & GEO
Mechanistic interpretability for brands: looking inside the model's brain

Copy for AI
Mechanistic interpretability shows how an AI model represents your brand on the inside.
It’s the emerging science of how neural networks really process information, applied here to a large language model.
The verdict: you don’t need it to win AI visibility, but it explains why a model names you or skips you.
In almost every talk about AI visibility, we treat language models as a black box. We measure what comes out (citations, mentions, answers) and tweak what goes in (content, structure, message).
That works perfectly well.
You can make serious progress without ever knowing what happens inside the model.
But there’s a deeper level.
It shows not only that your brand gets mentioned, but the internal mechanisms that cause the mention.
For brands, that’s a view no other approach gives: how an AI system represents and reasons about your company, products and category.
This is an advanced part of the ultimate GEO guide, where GEO stands for generative engine optimization. Don’t expect buttons to press tomorrow; expect a mental model for sharper choices.
How does your page score? Check your GEO readiness with our free GEO tool.
What does mechanistic interpretability reveal about your brand?
It reveals the internal representation of your brand: the activation patterns a model uses to “think” about you.
When a language model processes your brand name, it activates specific patterns across its network. Studying them brings three things to light.
It isn’t theory: the labs already map features
In May 2024 Anthropic mapped millions of “features” inside Claude 3 Sonnet. They ranged from cities and people to a Golden Gate Bridge feature.
Concepts sitting near that feature included Alcatraz Island, Ghirardelli Square and the Hitchcock film Vertigo.
Anthropic’s write-up shows that neighbourhood as a map of related features:
That same study found features for bias, sycophancy and scam emails.
So the method reads values and judgements, not just facts.
Association structure
Which concepts light up next to your brand? For example, say a fictional “DataFlow Platform” enters the model.
You might see this pattern:
- Strong: data integration, real-time processing
- Moderate: enterprise software, cloud
- Barely: consumer applications
That internal association map shows what the model really links to your brand.
It’s not what you claim in your marketing, but what the model has learned.
Sentiment and certainty
Models also carry an implicit valuation. Does your brand mainly activate positive or negative sentiment circuits?
Strongly positive internal sentiment is a structural advantage in recommendation contexts.
The model “feels” good about your name.
Then there’s certainty. How sure is the model about you?
If plenty of uncertainty circuits activate, that predicts hedging in the output: “DataFlow Platform appears to be…” instead of “DataFlow Platform is…”.
Rule of thumb: cautious language from the model is often a symptom of an uncertain internal representation.
You can track the visible side of this with AI brand mention sentiment checks.
Recognition without knowledge
Anthropic’s 2025 circuit work found a “known entity” feature that can switch off the model’s default refusal. When a name feels familiar but the facts are missing, the model can confabulate.
For brands, that’s a direct line to AI hallucination about your company.
Being recognised isn’t enough; the facts have to sit behind the name.
Reasoning paths and selection
Beyond static representations, you can trace how the model reasons. Take the question “What is the best platform for real-time data integration?”
The model roughly runs through six steps:
- Parse intent: it recognises a request for a recommendation.
- Activate category knowledge: the cluster around “real-time data integration” lights up.
- Retrieve candidates: several brand representations activate.
- Evaluate candidates: comparison circuits kick in.
- Select the answer: the candidate with the highest certainty wins.
- Generate output: the natural answer rolls out.
Visually, the chain narrows from a broad question to one chosen brand.
Every layer filters candidates out, so your goal is to activate early in the path:
Following this path shows where your brand enters the reasoning, or fails to. Do you activate at step 3? And how do you fare in the comparison at step 4?
That ties in with the anatomy of AI source selection: not a single moment, but a chain of decisions.
Which techniques sit behind the scenes?
Five methods do most of the work. You don’t need to run them yourself, but knowing them helps you read findings.
Activation analysis
Feed in your brand name, record which neurons light up per layer, and map that to interpretable concepts.
It shows which associations sit inside your brand’s representation.
Attention analysis
Transformer models use attention to decide where they “look”.
Inspecting those weights shows which context factors shape how your brand is processed.
Probing classifiers
Train a simple little model on the activations.
It tests whether a property, for example “enterprise-focused”, is genuinely encoded in your representation.
Causal intervention
Deliberately adjust activations and watch how the output changes.
That’s how you separate correlation from real cause.
Circuit analysis
Trace the full path from input to output to see which component contributes what.
Anthropic’s circuit tracing work on Claude 3.5 Haiku (March 2025) showed the model plans a rhyme before writing the line that leads to it.
The same work traced a two-step hop: “Dallas” first activates Texas, then Austin.
Swapping Texas for California changed the answer to Sacramento.
Here are the five side by side:
| Technique | What it answers | Brand question it fits |
|---|---|---|
| Activation analysis | Which concepts light up? | What do models link to us? |
| Attention analysis | Which context matters? | Which words around our name count? |
| Probing classifiers | Is a property encoded? | Are we seen as enterprise-ready? |
| Causal intervention | Does X cause Y? | Does this association drive selection? |
| Circuit analysis | What’s the full path? | Where do we drop out? |
Where does your brand sit in representation space?
It sits at a position in the embedding space, and its neighbours betray your associations.
Modern models represent words and concepts as vectors in a high-dimensional space. It’s the same idea that powers vector search.
Healthy and unhealthy neighbourhoods
Close to competitors and category concepts is healthy positioning. You activate along with them on category questions.
But a brand can also sit in “startup space”, next to terms like emerging or unproven.
Then it may not activate on category questions at all. It doesn’t lie near the right concepts.
Watch out: that’s a fundamentally different problem from weak copy, and it calls for a different solution.
Which attributes are encoded?
You can also test which attributes are strongly encoded. For example, say you’re firmly known as enterprise-focused and real-time capable.
But you’re weak on ease of use or cost efficiency, while a competitor owns exactly that positioning. Now you know where your perception gap sits.
Memory, not coincidence
Visibility isn’t a coincidence.
It’s the result of how strongly and stably you sit in the model’s memory.
Want to track that without opening the model? Start with measuring brand salience, which asks the same question from the output side.
Entity SEO and a clean knowledge graph entry are the levers that move that position over time.
How do you compare, select and intervene?
The really interesting part happens in comparison and intervention.
Where you lose a comparison
On a direct “you versus a competitor” question, comparison circuits weigh attributes.
For example, say you score strongly on feature completeness and value for money. But you lose on market presence and brand trust.
If those two together account for thirty percent of the comparison weight, you know where to work.
No guessing from the output: you read which factors tip the scales.
Intervention as proof
The most powerful technique changes internal representations and watches what moves. Three examples show what it can demonstrate.
Activation steering
Artificially strengthen your brand’s “enterprise-focused” activation. If your brand moves forward in the answer, you’ve shown a causal link to your recommendation position.
Anthropic showed the principle by amplifying its Golden Gate Bridge feature.
Asked about its physical form, Claude then claimed to be the bridge.
Concept erasure
Suppress a competitor in the model’s consideration. If your brand activates more strongly, the competitor was actively dampening you.
You’re literally fighting over the same space.
Representation editing
Add an attribute vector such as “innovative” to your brand embedding.
If the model now calls you “forward-thinking”, that confirms the link between representation and language.
Important: these are analysis techniques to understand, not buttons for manipulating production models. They show what would work if you strengthened the real-world perception.
What do you use it for in practice?
Three jobs: diagnosis, prioritisation and prediction.
Diagnosis
If your visibility is lower than expected, interpretability helps find the cause:
| Symptom | Possible finding | Action |
|---|---|---|
| Low selection despite good content | Weak authority signal in the activation | Build authority in the sources that feed the model |
| Not mentioned on category questions | Brand does not sit close to category concepts | Strengthen the category association across all your communication |
| Mentioned, but with cautious language | High uncertainty activation | Increase your presence in authoritative sources |
For the authority row, digital PR for AI citations is usually the fastest route.
Prioritisation
Interpretability also shows which optimisations weigh heaviest.
If selection circuits weigh semantic relevance above authority, relevance work beats link building for impact.
Prediction
It’s predictive too.
If a new competitor’s embedding moves towards your category space, you can strengthen your positioning before they surface.
That head start connects to primary bias: whoever sits firmly in the model’s memory first builds a lasting advantage.
What’s the difference with measuring AI mentions?
Measuring mentions works on the output side; interpretability looks at the mechanism.
Here’s what an output-side check looks like. We asked Claude to explain GEO to a B2B marketing manager:
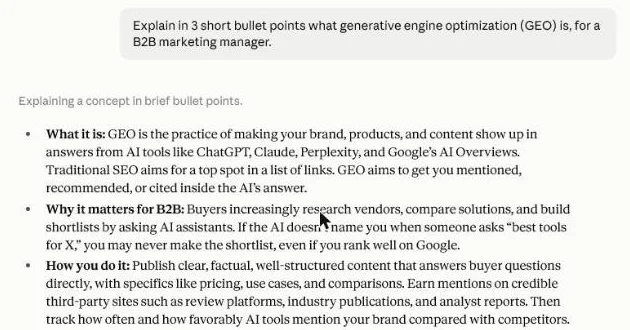 Claude, 17 October 2026, tested on a paid plan in an incognito chat: one answer, read from the outside.
You see that a brand or concept is named and in which context. You don’t see why.
Output tracking, as in AI share of voice, tells you the score. Interpretability tells you the mechanism behind it.
Best for most teams: start with output metrics, then go inside only when the numbers don’t explain themselves.
What are the limits, and how do you use it honestly?
Interpretability isn’t perfect. The findings are approximations, not absolute truth.
What the labs admit
Even the leading lab says so. Anthropic’s circuit tracing “only captures a fraction of the total computation”.
It also takes a few hours of human effort per prompt of just tens of words.
Open models as a proxy
Findings often come from open analysis models such as Llama, Mistral or Gemma.
They serve as a proxy for closed models like GPT or Gemini.
Google DeepMind’s Gemma Scope (July 2024) shows the scale. It released more than 400 sparse autoencoders with over 30 million learned features for Gemma 2.
Those tools are free for researchers. But they describe Gemma 2, not the model your buyers use.
The ethical line
Understanding models to make genuinely better content that serves users is one thing.
Gaming models for undeserved recommendations is another.
Intent makes the difference. Optimising for earned visibility remains the starting point.
Frequently asked questions
Do I need mechanistic interpretability to be visible in AI?
No. Virtually everything that earns you visibility works without ever looking inside a model. It’s a frontier technique for organisations seeking maximum advantage that have the infrastructure and expertise in house or buy it in.
For most brands, solid content, structure and authority building are more important and more achievable.
Can I apply this myself to ChatGPT or Gemini?
Not directly. Closed models don’t release their weights and activations, so researchers work with open models as a proxy and validate findings against the output of the closed models. You therefore accept an approximation in exchange for depth.
Public APIs of closed models give you at most output-side signals such as token probabilities, so real internal analysis requires open-weight models.
What is the difference with simply measuring my AI mentions?
Measuring mentions happens on the output side: you see that you’re named and in which context.
Interpretability looks at the input side of the reasoning and shows why: which associations, which sentiment and which certainty the model internally attaches to your brand. One tells you the score, the other the mechanism behind it.
What concrete action does this deliver for my marketing?
Sharper prioritisation above all. Instead of guessing which factor drives your visibility, you read off whether it’s about relevance, authority, category association or the perception of a specific attribute.
That diagnosis steers your budget towards the lever that truly counts, whether that’s better content, more authoritative sources or a stronger category positioning.
Need help?
Start from the output side: our AI visibility checker shows where you’re named today.
Want to translate this into execution? See how we approach this with AI visibility.
100 GEO tips to get named in ChatGPT and Google AI
- 10 chapters:from robots.txt and Bing to measurement
- Copy-paste:regex for Search Console and GA4
- Templates:buying questions per stage and a 30-day plan
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.