
SEO & GEO
What is a context window?

Copy for AI
A context window is the text an AI model can “see” at once.
In Dutch it’s called a contextvenster.
The model can weigh everything inside it while it builds an answer.
Anything outside doesn’t exist for it. Not at that moment.
The verdict: a bigger context window doesn’t mean your page gets read in full. Put the citable answer first, or it may never reach the AI answer.
Below: how it works, why size isn’t memory, and what it means for your AI visibility.
What is a context window exactly?
It’s the working memory of an AI model: the total amount of text it can hold at once for one answer.
That space holds everything relevant at that moment:
- the user’s question
- earlier messages in the same conversation
- instructions from the app or the user
- source text an AI search engine retrieved from the web
That last item is the one that matters for marketers. It’s where your page lands, or doesn’t.
How big is a context window in words?
The size is measured in tokens. A token is a piece of text, often a word or part of a word.
Rule of thumb: a token is about four characters in English, and 100 tokens is roughly 60 to 80 words, according to Google’s Gemini token documentation.
So a window of hundreds of thousands of tokens sounds abstract. In practice it’s hundreds of pages of text the model can survey in theory.
For instance, our wiki entry on tokens has the short definition if you need it for a briefing.
It’s temporary, not a memory
The important words there are “at once”. The context window isn’t permanent memory.
It’s a temporary space that’s filled again for every single answer.
What doesn’t fit is gone.
The same goes for an old conversation that dropped away. The model no longer knows it.
Why does a model have a limit?
Because processing context costs computing power, and that cost rises fast as the text gets longer.
The more tokens a model has to weigh at once, the more memory and compute each answer needs. A window is always a trade-off between how much you feed in and what stays technically and financially feasible.
How fast have context windows grown?
Spectacularly. Google’s long context guide sketches the jump in four steps:
Earlier generative models handled about 8,000 tokens at a time, the equivalent of a few pages.
Today many Gemini models accept 1 million tokens or more. Google puts that at roughly eight average-length English novels.
Or 50,000 lines of code, or transcripts of over 200 podcast episodes.
Why the growth matters
Bigger windows open the door to work on entire documents or long conversations at once. For example, a whole contract or a year of support tickets in one prompt.
But bigger isn’t automatically better. That’s exactly where the story for marketers starts.
Why is a large window not the same as a good memory?
Because a large context window says how much a model can load, not how reliably it uses all of it.
That distinction is often forgotten.
The “lost in the middle” effect
Research into long contexts keeps finding the same pattern:
- models do best on information at the start of the text
- they also do well on information at the end
- they more easily miss details buried in the middle
It’s called the “lost in the middle” effect, after a study by Liu et al.. It found performance drops significantly when the relevant information sits in the middle of a long context.
Google’s own long context guide is candid about a related limit. A model can find one “needle” well, but with many pieces of information to retrieve, “the model does not perform with the same accuracy”.
Advertised window vs effective context
So there’s a gap between the advertised window and the effective context.
A model can load hundreds of pages and still miss one crucial fact halfway through. The fuller the window, the bigger the chance a detail gets lost in the noise.
That’s no reason to distrust large windows. It’s a reason to understand how they behave, because it changes how you should write.
What does the context window mean for your AI visibility?
Put the most important answer up front and make it readable on its own, because a model doesn’t weigh your whole page equally.
Your page shares the window with other sources
When someone asks a tool such as ChatGPT, Perplexity or Google AI Overviews a question, the system usually retrieves relevant pieces from the web. It then places them together in the context window, next to pieces from other sources.
That retrieval step is called retrieval-augmented generation, or RAG.
Here’s what that looks like in Perplexity. Look at the number of sources behind a single answer:
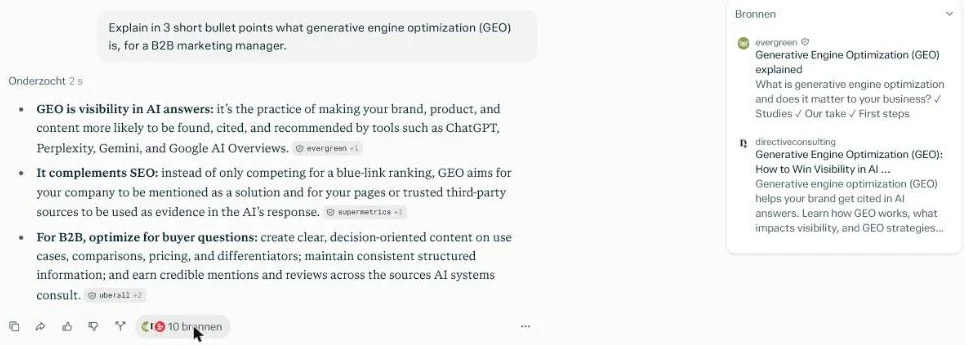 Perplexity’s sources panel for our own test prompt, 17 October 2026: 10 web pages behind one answer.
Ten pages competed for space in one window there.
Your page is one voice among many.
Not every source makes it into the answer
Retrieval isn’t the finish line either. Some systems look at a page and then drop it.
xAI’s developer docs say this plainly about Grok’s search tool:
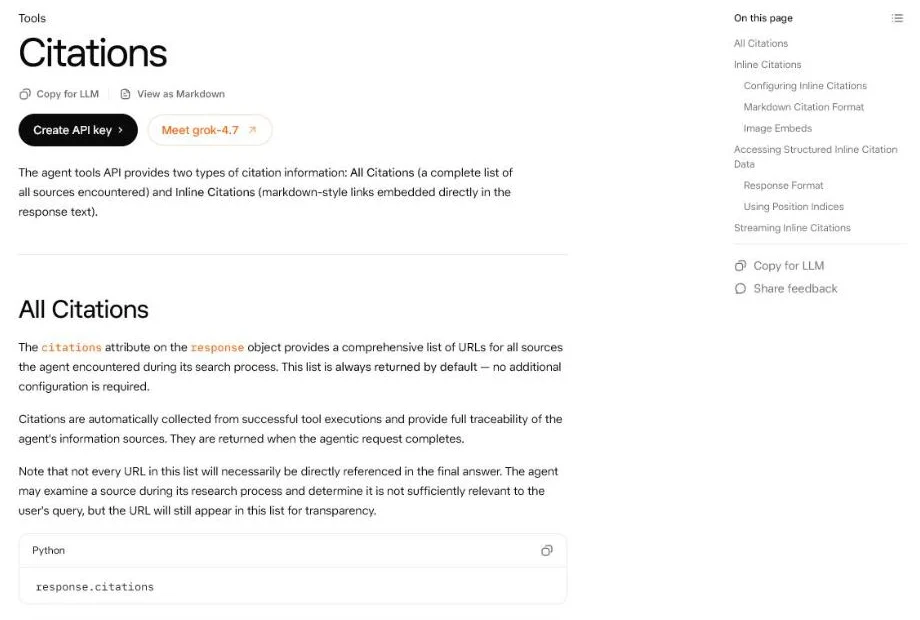 xAI’s developer docs on citations, October 2026. The agent may examine a source and drop it as not relevant enough.
So the piece of your page that lands in the window has to earn its place on its own.
The practical lesson
Say a long service page only gives the real answer in its last paragraph. It risks being ignored, even if that answer is excellent.
The chunk that gets retrieved may just not be the chunk where your key point sits. Content that gives a complete, citable answer up front has a far better chance of landing in the AI answer.
Our study of which sources ChatGPT cites shows the same preference for clear, self-contained passages.
How do you write content that survives a crowded context window?
Four habits, and they work regardless of which piece of your page gets retrieved:
- Answer at the top
- Write in self-contained chunks
- Keep the core out of the middle
- Be compact
1. Put the answer at the top
Begin each section with a complete, self-contained sentence that answers its heading. Build the nuance afterwards.
Example: under “How much does X cost?”, the first sentence names the price range. The caveats follow.
Your key message then works wherever the retrieval cuts in. That’s the point.
2. Write in self-contained chunks
Divide a long topic into bounded sections that each fully answer one question, with a clear heading above.
A chunk that’s understandable on its own survives better when it’s plucked from your page and dropped into a full window. We explain the method in content chunking for AI.
3. Don’t let the core disappear in the middle
Don’t hide your strongest argument or your key figure halfway through a wall of text.
What matters belongs where it stands out, such as the first lines of a section, a table or a short list.
Watch out: a key number inside a long paragraph in the middle of the page is exactly the “lost in the middle” spot.
4. Be compact where you can
The window is shared with other sources, so clear, dense content beats rambling text.
A sharp answer takes up less space. It’s easier to carry along. Our piece on semantic compression shows how to say more in fewer words.
A quick decision table
Use this to judge a page before you rewrite it:
| What you see on the page | Risk in a full context window | What to do |
|---|---|---|
| Answer in the first sentence of each section | Low | Keep it |
| Answer only in the conclusion | High | Move it to the top |
| Key figure buried in a long paragraph | High | Put it in a table or list |
| Sections that need the previous one to make sense | Medium | Rewrite each as a standalone chunk |
| Long intro before any answer | Medium | Cut the intro to one or two lines |
This approach fits how we look at content at Customer Impact. We don’t write to fill a window; we structure so the citable answer is always findable.
How to build pages that AI reads easily is covered in our article on content architecture for AI extraction.
How does this fit into the bigger AI search picture?
The context window is one link in a chain. It sets how much text a model processes at once.
But whether your content reaches that window at all depends on other mechanisms:
- Selection: how an AI picks and trusts sources falls under grounding
- Matching: how content and questions match on meaning runs on embeddings
- Extraction: which sentences get lifted is covered in grounding snippets
- The whole system: read our complete guide to generative engine optimization
Want to see where your own pages stand first? Run the free AI visibility checker.
If you want this turned into concrete actions that lead to AI mentions, leads and revenue, that’s the work of our GEO service for AI search engines.
There we make sure your content isn’t only good, but in the right place to be chosen.
Frequently asked questions
What is a context window in simple terms?
It’s the amount of text an AI model can look at in one go while it writes an answer. It’s measured in tokens, and anything outside it is invisible to the model for that answer.
Does a bigger context window mean AI reads my whole page?
No. A model can load a lot of text but still miss details in the middle of it. And AI search engines usually retrieve only pieces of your page, not the whole thing.
How many words fit in a context window?
It depends on the model. Google says 100 tokens is about 60 to 80 English words, and 1 million tokens is roughly eight average-length novels.
The short summary
A context window is the maximum amount of text, measured in tokens, that an AI model can process at once for one answer.
Windows have grown enormously. But a large window doesn’t guarantee everything in it gets used: details buried deep in a long text drop out easily.
So the lesson is simple:
- put your most important answer up front
- write in self-contained chunks
- don’t bury key points in the middle
That raises the chance AI takes exactly the piece that counts.
Want to know how well AI search engines pick up your content today? Contact us and we’ll show you which pages AI skips and what to fix first.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.