
SEO & GEO
The grounding snippet extraction framework: measure and optimise AI grounding snippets

Copy for AI
Grounding snippet extraction shows which passages AI grounding actually pulls from your page.
A citation only proves your page was used.
The grounding snippet extraction framework reverse-engineers which words the model took, so you can optimise the passage instead of guessing.
The verdict: stop optimising whole pages for AI. Measure which snippets get extracted, then strengthen those, because that’s where the selection decisions are made.
When we show a client that their page is cited in ChatGPT, that’s good news. They made the cut.
But then we ask the question that really matters: which words did the model actually use?
Their page runs to 2,500 words across twelve sections. The AI answer is 400 words, synthesised from six sources.
Somewhere in that synthesis sits their contribution. But which sentence, which section, which passage convinced the model?
Without that answer, optimising is guesswork. GEO (generative engine optimization) at page level is crude; this framework takes you down to snippet level.
This article is a deep dive within the ultimate GEO guide. For the basics of how models fetch sources, start with AI grounding.
Test your AI visibility: score your page in half a minute with our GEO check.
Why is a citation without extraction insight not enough?
Because you then optimise the parts of your page the model never used.
The problem is concrete. You know you were cited, but you don’t know what was used.
Three ways to miss
Here’s what that looks like in practice:
- You rewrite your introduction, while the model extracted from section eight.
- You add depth to your definition, while the model only wanted your statistic.
- You restructure the whole page, while one paragraph did all the work.
Every adjustment is a shot in the dark until you know which passage was selected.
Where you can see it, and where you can’t
Some AI answers show their sources per claim. Perplexity, for example, puts a source chip behind each bullet:
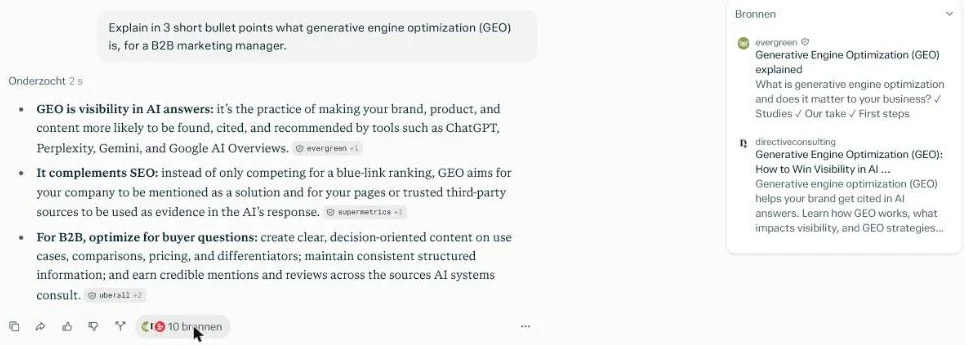 Perplexity’s sources panel for our own test prompt, 17 October 2026: 10 web pages behind one answer.
Even then, the chip names the page, not the sentence. Other answers show no sources at all:
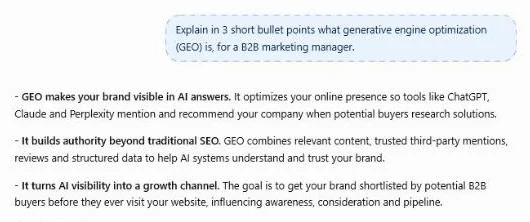 ChatGPT’s free answer to our own test prompt, 17 October 2026. No citations, so extraction can only be reconstructed from the text.
Precision turns chance into a system
Anyone who can identify which text was extracted gains precision. And precision lifts optimisation from chance to system.
This builds on the basics of grounding snippets.
That article explains what a grounding snippet is; this framework is about measuring and steering it.
What does extraction analysis reveal?
Patterns: which sections get used, what winning passages share, and which query pulls which passage.
As soon as you can see which fragments are used, your content becomes much easier to understand.
Extraction patterns per section
The first question: which sections get extracted most often? In practice, the value tends to be heavily concentrated.
Here’s an illustrative distribution (example figures, not a benchmark):
| Section | Extraction frequency |
|---|---|
| Definition (paragraph 1) | 73% |
| Feature comparison (section 4) | 45% |
| Process overview (section 2) | 38% |
| Case fragment (section 7) | 22% |
| Pricing summary (section 8) | 18% |
| Introduction | 4% |
| Conclusion | 2% |
In this example, the definition paragraph does the heavy lifting. The introduction and conclusion are all but invisible to AI extraction.
That’s a pattern you can measure on your own pages and act on.
Plotted as a bar chart, the concentration is obvious: a handful of sections pull in nearly all extractions.
Characteristics of extracted passages
Extracted and non-extracted passages differ systematically. What the winning fragments have in common:
- Shorter: compact paragraphs rather than long, sprawling sections.
- Readable on their own: they make sense without the surrounding text.
- Data-rich: they contain concrete figures or facts.
- Directly phrased: statements without hedging.
- Entity named explicitly: the product or brand is spelled out.
Non-extracted passages are longer, context-dependent and vaguer. They lean on the sentences around them.
This is the logic behind content architecture for AI extraction: you write fragments that stand up on their own.
Our guide to content chunking for AI shows how to cut them.
Rule of thumb: if a paragraph needs the one before it to make sense, a model is unlikely to lift it.
Query-passage mapping
Different questions extract different passages:
| Query type | Passage it tends to pull |
|---|---|
| ”What is …“ | your definition paragraph |
| ”How does it work” | your process overview |
| Comparison | your comparison table |
| Pricing | your pricing summary |
Once you know those mappings, you can optimise per query type instead of trying to improve the whole page.
Which four identification methods work?
Direct matching, semantic similarity, claim tracing and structural alignment, used together.
No single method is watertight on its own. Here’s how they fit:
1. Direct text matching
You compare the answer text with your source content and look for matching passages.
The problem: AI often paraphrases instead of quoting, and small word changes break an exact match. Fuzzy matching and spotting unique key sentences partly compensate.
2. Semantic similarity
You segment the answer and your page and turn both into vectors with an embedding model. Then you calculate the cosine similarity.
High scores point to an extraction relationship. It tolerates paraphrasing, since it’s comparing meaning rather than letters. Our explainer on embeddings covers the mechanics.
3. Claim-level tracing
You isolate every individual claim in the answer. Then you look for the passage on your page that most strongly supports it.
For example, an answer claiming “60% faster integration” leads you to the passage with exactly that figure.
Not to the vaguer variant that says “40% less time”.
4. Structural alignment
You recognise structural elements in the answer (lists, definitions, steps) and link them to the same structures in your content.
A three-point list in the answer that matches your “Key benefits” section with three bullets gives the source away.
The cross-encoder: the sharpest single tool
A cross-encoder deserves a separate mention.
Unlike embedding models, which process query and passage separately, it passes both texts through the model together and returns a single score.
That documentation says cross-encoders “achieve higher performance than Bi-Encoders”, but “do not scale well for large datasets”.
So the usual setup is retrieve and re-rank:
- embeddings to shortlist, for example the top 100
- a cross-encoder to re-rank that shortlist
Many public cross-encoders are trained on MS MARCO, a passage-ranking dataset built from real, anonymised Bing queries.
Its passage ranking set holds 8.8 million passages.
That’s why they’re a reasonable stand-in for search-style relevance judgements.
When you don’t have to guess
Sometimes the system tells you. The Gemini API, for example, returns citation annotations that link a span of the answer text (start and end index) to a source URL.
Where a system exposes that, use it as your ground truth. Then calibrate the four methods against it.
Which extraction metrics matter?
Four core metrics, plus citation coverage as the one to watch first.
The four core metrics
- Extraction rate: the share of citations where content of yours was actually used.
- Content utilization: what share of your content gets extracted.
- Passage concentration: how strongly extractions cluster on one section.
- Extraction stability: how consistently the same passages get used over time.
What each one tells you
A page can be cited without a single word extracted.
Your URL was listed, but another source supplied the substance; that’s what the extraction rate catches.
For utilisation, say your page has 10,000 characters and 800 are used on average. You’re at 8%.
Low utilisation points to content bloat, poor structure or a mismatch with the queries.
If 80% of extractions come from one section, that section does all the work. The others lie fallow.
Low stability can point to content sitting close to the selection threshold, or to shifting model behaviour.
These sit alongside the page-level GEO KPIs and your citation rate.
Citation coverage
The metric we look at most often is citation coverage: what share of your page content appears in AI answers when you’re cited.
There’s no public benchmark for it yet. So measure your own baseline first and compare pages against each other.
The bands below are our working rule of thumb, not industry data:
| Citation coverage | Interpretation |
|---|---|
| Under 20% | Most of it is invisible to AI: bloat, poor structure or mismatch. |
| 20 to 50% | Reasonable efficiency, with room for improvement. |
| Above 50% | Highly efficient, dense and well-aligned content. |
Targets per content type
The target depends on what the page is for:
- Definition content: aim for 60% or more.
- How-to guides: 40 to 50%.
- Comprehensive guides: 30 to 40%.
Watch out: never optimise coverage at the expense of readability. Some content serves the reader and not the extraction, and that’s fine.
How do you go from analysis to snippet optimisation?
Pick the passages that matter, then rewrite them to be self-contained, dense and direct.
Insight without action is worthless.
Three kinds of passages to fix
The analysis exposes three kinds of passages that deserve work:
- fragments retrieved but rarely selected, just below the threshold
- fragments tied to commercially valuable queries
- fragments where competitors get extracted in your place
Four techniques
For each type, these techniques make the measurement data actionable:
- Make the fragment self-contained: cut pronouns that refer elsewhere and name the entity explicitly.
- Raise the information density: out with filler sentences, in with concrete data points.
- Strengthen the direct answer: lead with the core information, in as few words as possible.
- Add unique value: your own figures, framework or example that the competitor lacks.
Naming the entity consistently is an entity SEO habit too. More rewrite patterns are in how to write content AI cites.
The competitive comparison
Put your passage next to a competitor’s for a query you’re losing. Often you see it straight away.
The winner has a specific metric, a concrete comparison point and an explicit product name. Your version stays vaguer and more general.
Those observations become your optimisation checklist.
Close the loop with citation mining
Connect the measurement to citation mining and the loop closes.
Measure which citations you get, trace which fragment produced them, and strengthen that fragment deliberately.
Start small
Don’t build a full pipeline right away. A minimal approach already works:
- Collect 20 to 30 AI answers that cite your content.
- Compare the answer text with your page by hand.
- Note which sections get extracted.
- Form hypotheses about what drives the selection.
- Adjust your content and see what shifts.
Only once that pattern proves itself is it worth automating the capture, matching and reporting.
Frequently asked questions
What is the difference between a citation and an extraction?
A citation means your URL is mentioned as a source in the AI answer.
An extraction means text of yours is actually woven into the answer.
The two don’t always coincide: a model can cite your page but take the substance from another source.
The extraction rate measures how often a citation turns into content that’s genuinely used.
How accurately can you reconstruct which fragment was extracted?
That depends on the method, and there are no published accuracy benchmarks for this exact task.
By design, exact text matching misses paraphrases, semantic similarity tolerates them, and a cross-encoder re-ranker is usually the sharpest single method.
A combined approach, where you lay several methods side by side and reconcile the results, is the most reliable.
Factual and structured content reconstructs more reliably than narrative text.
Where the AI system returns span-level citations, as the Gemini API does, you can check your reconstruction against them.
Which metric should I track first when starting out?
Start with citation coverage and extraction rate. Coverage tells you which part of your page is visible to AI at all.
The extraction rate tells you whether your citations turn into content that’s genuinely used.
Together they give the fastest read on whether the problem is visibility or utilisation.
Does the extraction pattern change over time?
Yes, and you need to account for that.
For identical content, the extraction rate can drop as the page ages, a sign of freshness factors.
On top of that, model updates, competitor changes or shifting query intent can make the same question pull a different passage.
That argues for regular content refresh and periodic re-measurement.
Need help with grounding snippet extraction?
Start with 20 citing answers and one spreadsheet this week.
Want to translate this into execution? See how we approach this with AI visibility, and track progress in a GEO dashboard.
100 GEO tips to get named in ChatGPT and Google AI
- 10 chapters:from robots.txt and Bing to measurement
- Copy-paste:regex for Search Console and GA4
- Templates:buying questions per stage and a 30-day plan
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.