
SEO & GEO
Prompt monitoring explained: tracking your brand in AI answers

Copy for AI
Prompt monitoring tracks how your brand shows up in AI answers.
It covers ChatGPT, Perplexity, Claude and Google AI Overviews.
Instead of checking a position in blue links, you check whether an AI names you when someone asks a buying question.
The verdict: if buyers ask AI assistants for a shortlist, prompt monitoring is the only way to know you’re on it.
You look at four things per answer: are you named, where, with which source and in what wording.
What is prompt monitoring?
Prompt monitoring is a measurement discipline for AI answers.
It records whether, how and why your brand surfaces when an assistant generates a reply.
You build a fixed set of questions (“prompts”) your buyers would really ask. Then you run them again and again.
The four signals per answer
For each answer, you typically record:
- Mention: are you named at all?
- Position: where do you sit in the list of options?
- Citation: which source does the model use to name you?
- Tone: how are you described, and in what context?
Together, those signals show your presence in the answers people base decisions on.
The measuring side of GEO
Prompt monitoring is the measurement side of Generative Engine Optimization.
GEO is about being visible and correctly understood in AI systems.
Prompt monitoring tells you whether that work is having an effect.
It’s the AI version of rank tracking in classic SEO.
The difference: you’re no longer measuring blue links, but generated recommendations.
Here’s what one check looks like in practice. We asked ChatGPT for AI visibility tools and noted who it named:
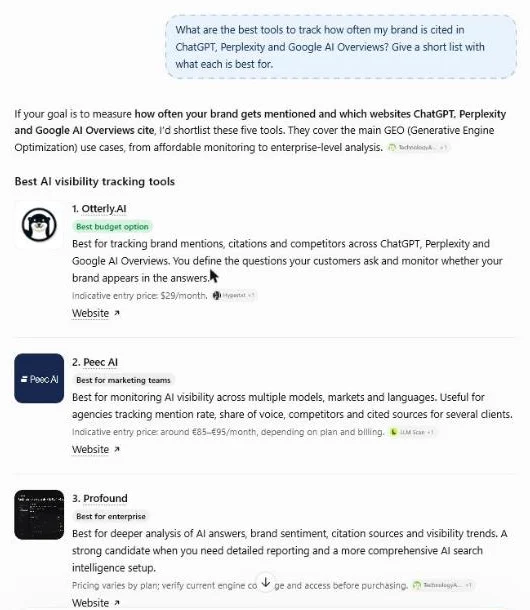 Our own ChatGPT test on 17 October 2026. Prompt monitoring logs who’s named, in which order and with which label.
One answer like this is a data point, not a result. So the method relies on repetition.
Why do you need prompt monitoring?
Because AI answers are invisible and unstable.
Without measurement, you don’t know whether a buyer saw your brand at the moment that counted.
AI answers leave no report
That invisibility is the core problem.
With Google, Search Console shows which queries you appear for and how many clicks they bring. Even there, Google folds AI Overviews and AI Mode traffic into the regular “Web” search type, without a separate AI view.
A standalone AI assistant usually gives you no click and no report at all.
The user asks, gets a summary and acts on it.
You have no idea whether your name was in it.
Prompt monitoring makes that blind spot measurable.
The same question gives different answers
On top of that, AI answers vary.
Models work with built-in variation, live retrieval of sources and context from location and earlier chats. So the same question can produce two different answers.
We explain why in our piece on the probabilistic nature of AI answers.
Ask once and your brand comes up? That may be chance.
SparkToro tested this in 2,961 runs across ChatGPT, Claude and Google’s AI. The odds of getting the same brand list twice were under 1 in 100.
The same order? Only about 1 in 1,000 runs.
So only repeated measurement shows a pattern instead of a snapshot.
Buyers now start in AI chatbots
This channel has become too important to steer on gut feeling.
In G2’s March 2026 survey of 1,076 B2B software buyers, 51% said they start research with an AI chatbot more often than with Google.
A year earlier, that was 29%.
AI chatbots are now the top source shaping their shortlists.
If you’re not on that list, you’re not even considered.
Our view: we’d rather steer on revenue and leads than on vanity metrics.
But first you need to know you’re in the picture.
How does prompt monitoring work in practice?
It rests on one principle: measure the same prompts repeatedly, across several models, and compare.
The approach has four steps:
- Build a measurement set of prompts that reflect your audience’s real questions.
- Run them on the assistants your buyers use, such as ChatGPT, Perplexity and Google AI Overviews.
- Record mention, position, source and tone for each answer.
- Repeat on a fixed cadence, so you see change and not one lucky result.
Measure each prompt several times
The crucial part is that you measure each prompt more than once.
Because answers fluctuate between sessions, a single check says little.
Ask the same question repeatedly and you get a mention rate: “in this share of runs, we were named”.
That percentage is the honest metric.
SparkToro’s authors go further: they advise running a prompt at least 60 to 100 times and tracking a visibility percentage rather than a ranking position.
Our experience: 10 prompts is too few to be statistically meaningful.
We start from a baseline of about 100 non-branded questions from the bottom and middle of the funnel.
Measure per model
Just as important: measure per model.
ChatGPT, Perplexity and Claude gather answers in different ways.
They also name brands to very different degrees.
A healthy picture in one model doesn’t mean you’re visible in another.
Track only one assistant and you miss half the picture. A cross-model GEO analysis shows where the gaps are.
Perplexity makes the source side easy to see. Each answer lists the pages it drew on:
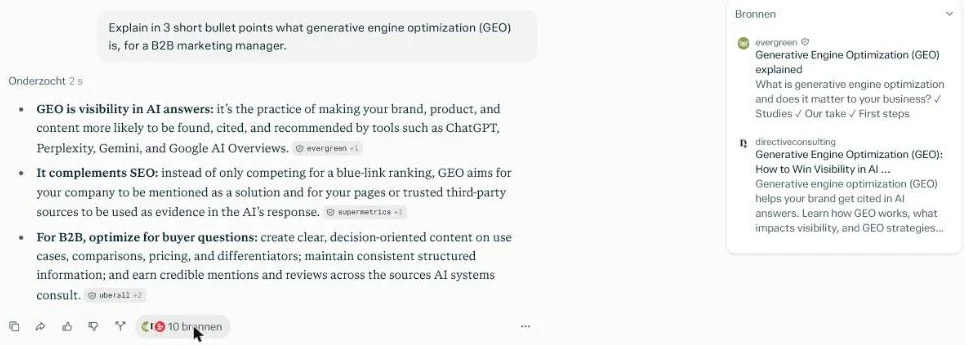 Perplexity’s sources panel for our own test prompt, 17 October 2026: 10 web pages behind one answer.
Those sources tell you where to earn mentions.
That’s half the value of monitoring.
Tools versus manual checks
Specialized AI visibility tools automate this and sample at scale.
Our overview of GEO tools compares the main options.
Most show the result as a dashboard per competitor:
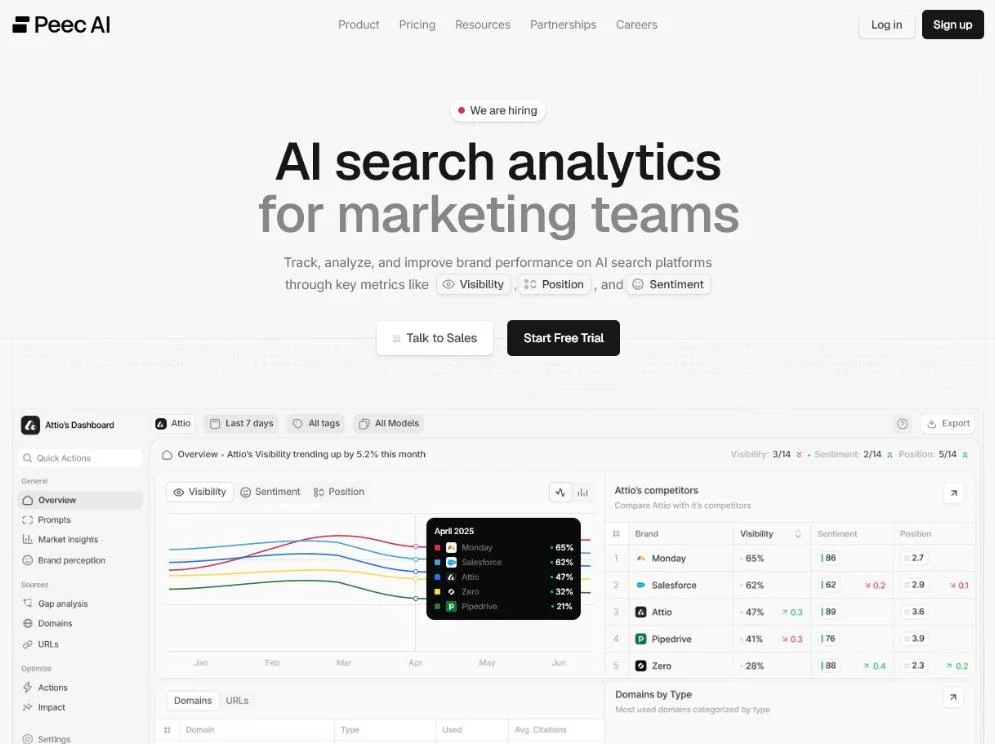 Peec AI’s homepage, October 2026. Visibility, sentiment and position sit next to each competitor.
Our Peec AI review covers what that tool measures well and where it stops.
You can start small with manual spot checks.
Our guide to measuring AI visibility without tools shows how.
Rule of thumb: for an ongoing, reliable picture, a tool that measures several times a day is all but indispensable.
What a mention rate shows over time
Here’s our own site as an example. We track 125 agency-choice prompts in Perplexity:
Perplexity now names us in 16 of those 125 prompts, up from 7.
That’s a move from 5.6% to 12.8%.
A single check could never show that shift. A fixed prompt set can.
Which prompts should you track?
Track the real buying questions of your audience, not the abstract keywords from your old SEO list.
People talk to an AI assistant in full sentences, with context.
Nobody types “fleet management software” and stops there.
They ask: “what’s the best fleet management software for transport companies in Belgium?”
So you build your set around concrete, intent-rich questions like that.
Four prompt categories
Think in four categories:
- Category questions: “best [type of solution] for [audience/sector]”. Do you make the shortlist at all?
- Comparison questions: “[your brand] vs [competitor]” or “alternatives to [competitor]”. How are you positioned?
- Brand questions: “what does [your brand] do” or “is [your brand] reliable”. Does the model describe you correctly?
- Problem questions: questions where you don’t appear yet, but your solution fits. That’s your growth potential.
Our guide on which prompts to track goes deeper into each category.
Keep the set focused
Keep the set deliberately relevant.
A handful of prompts that match your sales conversations beats a hundred questions nobody asks.
Start with the questions closest to a purchase decision. That’s where visibility is worth the most.
For example, say you sell HR software to Belgian SMEs.
“Best payroll software for small companies in Belgium” belongs in the set. “What is payroll?” probably doesn’t.
Watch out: don’t stop at a dozen prompts. Focus on buying questions, then cover them at volume.
How often should you do prompt monitoring?
Continuously, because both the models and your visibility keep changing.
Prompt monitoring isn’t a one-off audit.
It’s an ongoing measurement.
Two reasons for a fixed cadence
Two kinds of change make a fixed rhythm necessary:
- Model updates: models are updated or replaced, and your position can shift overnight.
- Live sources: many assistants retrieve the web live, so the answer moves when sources change.
Without periodic measurement, you only notice a decline once the leads have dried up.
Our experience: models drift, so our prompt monitoring runs every few hours, not once a month.
A workable rhythm for B2B
For most B2B companies, a fixed monthly report of your core prompts works well.
Underneath it, more frequent automated checks catch the fluctuation.
Around big moments, you measure more intensively:
- after an announced model update
- after an important content publication
- after a campaign meant to lift brand mentions
The goal isn’t measuring for its own sake.
It’s seeing in time when something moves, so you can adjust.
What to record, and what to do next
Which metrics to record each round?
We work that out in the five key indicators of AI visibility. Share of answers against competitors is covered in our piece on AI share of voice.
Some AI clicks do reach your site.
Our guide to tracking ChatGPT traffic in GA4 shows how to see them.
If visibility disappoints, the fix is rarely more measuring.
It’s often stronger, consistent brand mentions that teach models to link you to the right question.
Measure first, then fix the gaps.
Frequently asked questions about prompt monitoring
How many prompts should you monitor?
Enough to be statistically meaningful. In our work, 10 prompts is too few; we start from about 100 non-branded buying questions.
How often should you run each prompt?
Repeatedly, because answers change between sessions. SparkToro advises at least 60 to 100 runs per prompt, averaged into a visibility percentage.
Is prompt monitoring the same as rank tracking?
No. Rank tracking measures a fixed position in search results, while prompt monitoring measures how often and how an AI names you.
Can you do prompt monitoring manually?
Yes, for a first baseline. For an ongoing picture across models, a tool that samples several times a day works far better.
The short summary
Prompt monitoring tracks how your brand appears in AI answers: named or not, position, source and tone.
You need it because AI answers are invisible and variable. So you:
- measure the same prompts repeatedly, across several models
- build the set around real buying questions
- run it on a fixed cadence, not once
It’s the measurement side of GEO.
Without it, you can’t tell whether your AI visibility work pays off.
Want to know how often AI names your brand today? See our approach to generative engine optimization or contact us for a first baseline.
Free website scan
Enter your website and get an automatic scan within minutes, with concrete technical and SEO improvements. No sales pitch.
We only use your details for your scan. No spam, unsubscribe anytime.